

H2O Lightning
Collection
Lightning models and project artifacts. Public releases are visible; private work remains restricted until approved. • 21 items • Updated • 4
H2O-Lightning-4B is a 4B-parameter decision model from H2O.ai, built on Qwen/Qwen3.5-4B. It answers typed decision questions about a record (a document, a ticket, a policy, a conversation) and about images that come with the record (photos, screenshots, scanned documents, charts). It returns a probability for every option:
noul): gives the probability that a statement is true;It runs on unmodified vLLM 0.30.0 with a small standard-library shim in front (h2o_lightning_shim.py). Each
decision is one forward pass and one output token, so the cost is input tokens only. Since v1.3 the weights read a
prompt in either of two ways, two-way (the recommended default) or one-way; see
Two-way reading.
Try it in your browser: live demo on Hugging Face Spaces (text and images; built by the Hugging Face team and running on ZeroGPU).
H2O-Lightning-4B v1.1 has been #1 on the official JevBench Composite Score of open-weight systems from October 7 through October 16, 2026, across JevBench versions v1.6.1 through v1.7.46, including every model added in that time. It outscores Jev itself: 72.5 to 71.5, and is ahead of every open 12B, 26B and 31B model on the board. (leaderboard, read 2026-10-07 and 2026-10-16)

| Composite | Intelligence | Calibration | Speed | Cost | $ per 1,000 decisions | |
|---|---|---|---|---|---|---|
| H2O-Lightning-4B v1.1 (4B) | 72.5 | 60.0 | 90.0 | 92.6 | 60.3 | $0.021 (est.) |
| Jev 1.13.0 (reference, hosted) | 71.5 | 63.6 | 90.6 | 91.5 | 54.7 | $0.032 |
| Quyet-1.0-Large (31B) | 71.4 | 73.4 | 90.0 | 86.9 | 50.5 | $0.045 (est.) |
The composite is the equal-weight harmonic mean of the four axes. The 31B models lead on raw intelligence, while this 4B matches their calibration at a fraction of the cost and latency.
| Four axes, against a 31B | Capability against cost |
|---|---|
 |
 |
Microsoft's Microsoft-Decision-1 announcement compares accuracy, latency and calibration side by side. The chart below keeps Microsoft's accuracy numbers unchanged, corrects the latency and puts it on one H100 basis, and shows both JevBench v1.6.1 scores. Each model has composite above capability; the animation sorts by composite, capability, latency and accuracy. Capability averages Intelligence and Calibration, excluding speed and cost.


Footnote: we corrected the latency from Microsoft's page. For self-hosted models it used the leaderboard's adjusted
figure (measured time x 2 + 0.15 s, which the board itself labels "assumption, not measured"), so this model appeared
at 210 ms instead of its measured 29 ms. The chart uses the board's measured median (latency.p50_s_raw in the
JevBench v1.6.1 data) on one H100 basis: Quyet-1.0-Large (116 ms)
and deck-31B (127 ms) were timed on an H100 and are unchanged; Surogate Rune was timed on an RTX PRO 6000, which has
about half an H100's memory bandwidth and compute, so its 116 ms is halved to 58 ms (the most favourable conversion for
it); this model was timed by the board on an RTX 5090 at 29 ms, and our own serial H100 runs give 28-32 ms, so 29 ms is
kept. Microsoft-Decision-1 now uses JevBench’s measured API median 460 ms (replacing Microsoft’s announcement’s 85 ms), with composite 69.1 / API #6. OpenAI Decisions uses 298 ms (about 0.30 s), with composite 62.5 / API #8. Both and Jev include network time and are not rescaled. The accuracy numbers are
Microsoft's own, on benchmarks they chose, so they are likely to favour their model; the JevBench composite is scored on
held-out items that no submitter, us included, has seen. Composite and ranks: open-weights
and API boards, read 2026-10-10.
How we got there:
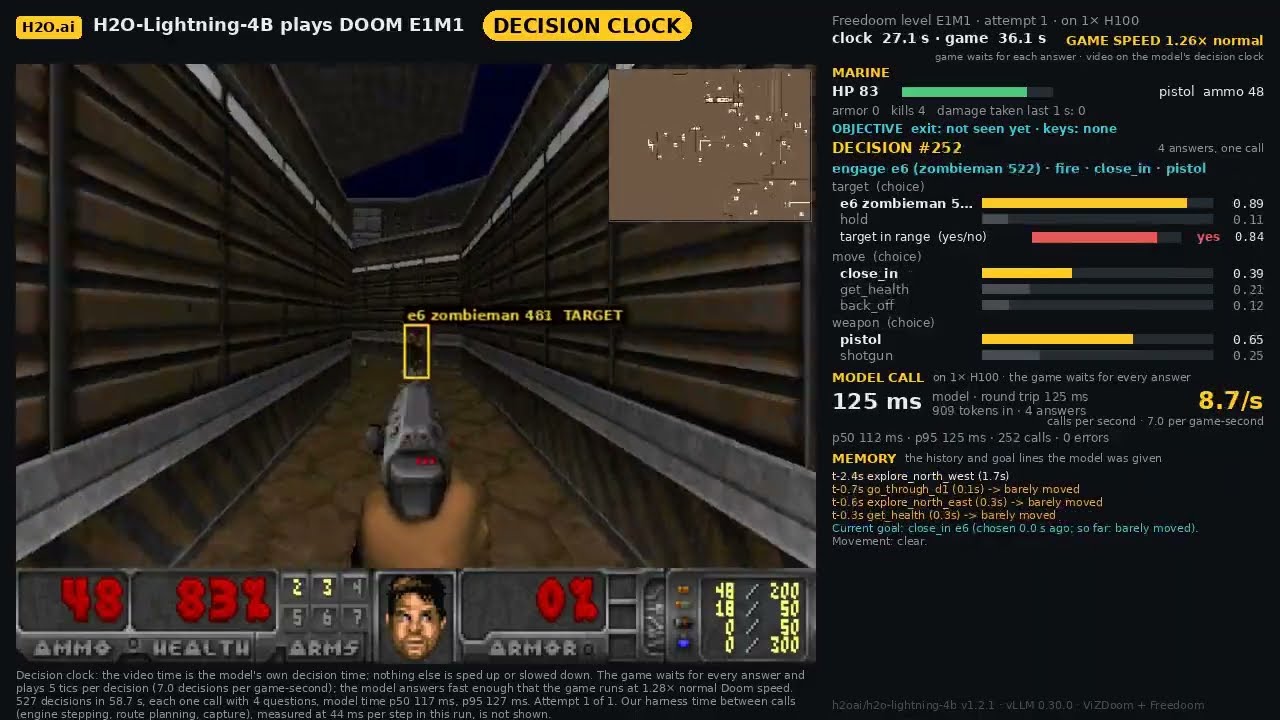
Three live runs on one NVIDIA H100 (vLLM 0.30.0). The operations inbox and the web agent are shown in real time: nothing is sped up or slowed down. DOOM, where the game waits for each answer, is shown on the model's decision clock, which advances only by the model's own time per call. Companies, people and amounts are fictional.
One panel, three demos in turn: operations inbox (1,000 claims against a written policy, 32 at a time on one GPU, all decided in 63 s), web agent (8 real browsers, 192 vendors in 145 s, every decision correct against answers written beforehand) and DOOM (a Freedoom level played to the exit, four decisions per call). Each demo is followed by what was checked afterwards. The clips are excerpts; the full runs follow.
Full-length runs (uncut), on YouTube. The same three demos, each run shown complete, with chapters. In DOOM, E1M1 is one of the two maps the thin controller (aiming, routing) was tuned on; the model itself was never trained on Doom.
Which weights. main carries the v1.3 weights (tag v1.3), trained for both attention patterns (see
Two-way reading). The JevBench board scores (the #1 claim above) are the v1.1
weights (tag v1.1, the revision submitted to the board); everything in this section from "Measured on one NVIDIA
RTX PRO 4500" onward was measured on the v1.2.3 weights (tag v1.2.3); the next two tables and the Decision
Index paragraph are the v1.3 weights. The v1.3 weights' own results on the same public
items, through the same CLI and shim on one NVIDIA L40S (48 GB), vLLM 0.30.0, through serve.sh (no flags for
two-way, TWO_WAY=0 for one-way; all 231 answered and valid in both modes; no yes/no answer between 0.2 and 0.8;
client latency p50 40 ms serial):
| v1.3 weights, JevBench's 231 public items | correct | by tier: easy / standard / hard |
|---|---|---|
two-way reading (the default; bash serve.sh) |
202 / 231 (87.4 %) | 48/48 · 70/72 · 84/111 |
one-way reading (TWO_WAY=0; stock generate-mode vLLM) |
198 / 231 (85.7 %) | 48/48 · 70/72 · 80/111 |
v1.2.3 weights, for comparison (--revision v1.2.3) |
205 / 231 (88.7 %) | 48/48 · 71/72 · 86/111 |
On JevBench's public items the v1.3 weights are 3 (two-way) and 7 (one-way) items behind v1.2.3 (paired against the
v1.2.3 run: two-way gains 4 and loses 7, exact McNemar p = 0.55; one-way gains 4 and loses 11, p = 0.12: neither
difference is significant); two-way is ahead of one-way on them. Pin --revision v1.2.3 for the measured
configuration below (--revision v1.1 for the board's weights); use main for two-way reading.
Decision Index 0.3 public suite, our own run with the official scoring kit, at the shipped temperatures and
yes/no floor, with max_state_tokens raised to 1000000 for these runs (shipped: 32000) so that no record was trimmed: text 57.10 two-way / 55.88 one-way (140,178 scored rows);
vision 68.00 two-way / 67.57 one-way (public vision half, 12,210 rows). The score is the kit's DI index (0-100),
not percent correct; the leaderboard's private half was not run. Both modes were scored with the same temperatures
and yes/no floor, the released one-way values (choice 0.75, yes/no 0.8, score 0.65, floor 0.801, images 0.65):
nothing was fitted separately for two-way, so serve_config.json's two_way block carries those values as an
interim calibration, and a two-way fit may follow in a later revision. A parity check of the pooled readout against
vLLM's log-probability readout with the same (one-way) attention agreed on 99.32 % of 293 vision questions (median
|dp| 0.0005) and at the 99.5-99.8 % bar on text, so the two-way numbers are a property of the attention mode, not of
the readout.
Measured on one NVIDIA RTX PRO 4500 Blackwell (32 GB) with serve.sh as shipped (vLLM 0.30.0; text temperature
0.8, image temperature 0.65, images up to 1,048,576 pixels), v1.2.3 weights:
| JevBench | public items | result |
|---|---|---|
| JevBench (text) | the 231 public items, JevBench's own CLI | 205 / 231 (88.7 %): easy 48/48 · standard 71/72 · hard 86/111 |
| ImageJevBench | the 8 published examples (the only public items released with images) | 8 / 8 |
| image validation sets | 1,877 questions over 16 public licence-clean sets (table below) | 87.4 % |
Details follow.
From JevBench's own CLI, with --adapter typesafe, on the 231 public items (datasets/public/easy.jsonl,
original.jsonl and hard.jsonl; dataset hash dc3995d8…) at JevBench commit bb05a33, with the commands below.
The measured H100 was an 80 GB SXM5, with a 700 W configured power limit (board692-2G520-0200-000). These are not H100 PCIe measurements; the timing values below are unchanged.
| RTX PRO 4500 Blackwell 32 GB | 1x H100 80 GB SXM5 | |
|---|---|---|
| correct | 205 / 231 (88.7 %) | 205 / 231 (88.7 %) |
| by tier: easy / standard / hard | 48/48 · 71/72 · 86/111 | 48/48 · 71/72 · 86/111 |
| answered and valid | 231 / 231 | 231 / 231 |
| yes/no answers with P(yes) strictly between 0.2 and 0.8 | 0 of 74 | 0 of 74 |
| mean input tokens per decision | 654 | 654 |
| client latency p50 / p95, standard 72 items, serial | 29.6 ms / 29.8 ms | 28.8 ms / 29.3 ms |
| client latency p50 / p95, all 231 items, serial | 30.2 ms / 225.6 ms | 29.8 ms / 69.9 ms |
| server-reported latency p50 / p95, all 231 items, serial | 30.0 ms / 225.3 ms | 29.5 ms / 69.5 ms |
| raw LoRA: correct, separate run | 205 / 231 (88.7 %) | 204 / 231 (88.3 %) |
| raw LoRA: client latency p50 / p95, standard 72 items, serial | 57.3 ms / 58.0 ms | 69.2 ms / 72.1 ms |
| raw LoRA: client latency p50 / p95, all 231 items, serial | 58.0 ms / 272.6 ms | 70.7 ms / 148.1 ms |
| raw LoRA: server-reported latency p50 / p95, all 231 items, serial | 57.9 ms / 272.4 ms | 70.4 ms / 147.7 ms |
Latency rechecked October 10, 2026, using the exact v1.2.3 release
(acaf0d4ea251e54de928c75ef4352670d33192d3). Each GPU processes the same
231 distinct public requests once, one request at a time, over a persistent
localhost HTTP connection. Server startup, compilation, and 10 separate warmup
requests are excluded from both client and server timing statistics. No
cached repeat passes are included; the measured pass had zero prefix-cache
hits on both GPUs. Client latency covers the complete shim request and
response; server latency is the shim's reported processing time. Both use
BF16, 40,960-token context, default CUDA graphs and prefix caching, with matched
vLLM 0.30.0 / Torch 2.13.0 cu129, Transformers 5.19.0 and tokenizers 0.23.3.
Separate raw LoRA measurement: the additional rows use the released adapter from
that same pinned v1.2.3 revision on Qwen/Qwen3.5-4B revision
851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a, with its standard alpha/rank scaling
(128/64), deployment multiplier 1.0, BF16 and max_num_seqs=64.
The preceding rows measure the merged checkpoint with its shipped server defaults.
These are two deployment configurations and separate weight representations.
The LoRA run uses the same pinned runtime, calibration, 40,960-token context,
CUDA graphs, prefix caching, 231 distinct serial requests, and ten separate
warmups excluded from both timing statistics. Native loading and activation of
all 496 adapter tensors across 248 decoder projections were checked; separate
base→adapter→base controls verified an adapter effect and restored base routing.
The H100 LoRA run scored 204/231, compared with 205/231 on RTX, using the same pinned adapter and calibration.
For the merged-model rows, the wider p95 is across different prompt lengths, not parallel traffic: the standard prompts contain 110–163 input tokens, while the hardest include up to 3,952. That longest request took 316.5 ms on RTX and 85.9 ms on H100. These are single-request timings, not throughput or concurrent-load measurements; latency depends on the GPU and input length. JevBench's own measurement of v1.1: median 29 ms (board data, latency.p50_s_raw).
Identity check for the merged-model evaluator: a correct setup reproduces 205/231 with the tier split above. Five hard items
sit on near-ties (top two within 0.03) that GPU numerics can flip. Four are wrong here:
hard-opus-a-temporal_numeric-07, hard-opus-a-temporal_numeric-12, hard-opus-c-temporal_numeric-04 and
hard-sol-b-temporal_numeric-03. One is right: hard-sol-c-judge_hard-13.
(a) The published ImageJevBench examples: 8 / 8. ImageJevBench's own harness is not public, and only 8 of its items are published with their images (on the benchmark's page: two everyday photos, four screenshots with five labelled click markers, one geometry diagram, one financial table). We read all 8 through this API: 8 correct. These 8 items are not a benchmark score.
(b) Public validation sets with human or source ground truth. Multiple-choice questions we built from each
dataset's own annotations (human labels, boxes, receipt fields, table cells, a chart's own data); none come from a
model. None of these images or questions was used for training. Read through this API, one image per request, as a
data URI in state.
| set (licence) | what is asked | n | correct | ECE |
|---|---|---|---|---|
| Open Images V7 validation (CC BY 4.0 annotations) | is there a ‹class› in the photo (human-verified labels) | 150 | 88.0 % | 0.034 |
| Open Images V7 validation | how many ‹class› in the photo (human boxes, 2-8) | 150 | 63.3 % | 0.121 |
| VizWiz validation (CC BY 4.0) | can the question be answered from this photo | 120 | 84.2 % | 0.057 |
| VizWiz validation | the answer (6+ of 10 annotators) | 120 | 100.0 % | 0.015 |
| TextVQA validation (CC BY 4.0) | text in the photo (6+ of 10 annotators) | 120 | 99.2 % | 0.024 |
| CORD v2 test + validation (CC BY 4.0) | receipt total | 95 | 99.0 % | 0.014 |
| CORD v2 test + validation | one item's price | 29 | 96.5 % | 0.043 |
| CORD v2 test + validation | number of item lines | 113 | 85.0 % | 0.050 |
| TAT-QA dev (CC BY 4.0) | financial-report table questions (the table shown as an image) | 120 | 95.8 % | 0.037 |
| DocLayNet test (CDLA-Permissive-1.0) | which section heading is on the page | 120 | 100.0 % | 0.011 |
| DocLayNet test | how many tables are on the page (0-3) | 120 | 75.8 % | 0.057 |
| DocLayNet test | does the page contain a picture | 120 | 90.0 % | 0.039 |
| Our World in Data charts (CC BY 4.0) | which country is highest or lowest (the chart's own data) | 100 | 98.0 % | 0.058 |
| Our World in Data charts | did a value rise between two years | 100 | 95.0 % | 0.069 |
| Our World in Data charts | roughly what is a value | 100 | 98.0 % | 0.066 |
| Rico app screens (CC BY 4.0) | which of 5 marked elements reaches a goal (human widget captions) | 200 | 65.0 % | 0.094 |
| all | 1,877 | 87.4 % | 0.017 |
ECE: 10-bin expected calibration error of the top answer's probability.
When a decision is uncertain you may want to hand it to a stronger model or a person. This table shows that trade-off: at a confidence threshold, how many questions get escalated (top probability below the threshold) and how many slip through confidently wrong (top probability at or above it, but wrong), as a share of all questions.
Measured (v1.2.3 weights, one-way) on 3,474 held-out questions from two public third-party decision sets, with no overlap with our training data; text temperatures as shipped (choice 0.75, yes/no 0.8, score 0.65). The thresholds were fixed before the analysis was run.
| question type (n) | threshold | escalated | accuracy on the rest | confidently wrong |
|---|---|---|---|---|
| choice (1,854) | 0.8 | 34.1 % | 95.5 % | 3.0 % |
| choice | 0.9 | 47.5 % | 98.2 % | 1.0 % |
| yes/no (1,367) | 0.8 | 40.8 % | 96.0 % | 2.3 % |
| yes/no | 0.9 | 59.5 % | 99.1 % | 0.4 % |
| score (253) | 0.8 | 46.2 % | 96.3 % | 2.0 % |
| score | 0.9 | 59.7 % | 98.0 % | 0.8 % |
| all (3,474) | 0.8 | 37.7 % | 95.8 % | 2.6 % |
| all (3,474) | 0.9 | 53.1 % | 98.5 % | 0.7 % |
Without a threshold, accuracy is 82.7 % (choice), 84.7 % (yes/no) and 80.2 % (score).
The per-question predictions behind this table, the converted questions (with their sources and licences) and a
script that recomputes it at any threshold, temperature or escalation budget are in
routing_reproducibility/. A re-read moves the small score cells (253 questions) by about
one question: at threshold 0.9 the re-read in that folder gives 99.0 % accuracy on the rest instead of 98.0 %, because
one wrong score question sits right at the threshold (0.896).
These numbers use routing mode (the yes/no floor off), for deployments behind a fallback. As shipped (the evaluated configuration), yes/no answers are reported at no less than 0.801, so none would be escalated below 0.8.
Hardware measured: one RTX PRO 4500 Blackwell (32 GB); the weights (model.safetensors) are 9.3 GB. Install vLLM 0.30.0 in a fresh virtual environment
(for example python3 -m venv .venv && . .venv/bin/activate):
pip install "vllm==0.30.0+cu129" "torchcodec==0.16.0+cu129" --extra-index-url https://wheels.vllm.ai/0.30.0/cu129 --extra-index-url https://download.pytorch.org/whl/cu129
The shim needs Python 3.8 or later and nothing else.
hf download h2oai/h2o-lightning-4b --local-dir h2o-lightning-4b
That is main: the v1.3 weights, both reading modes, the Box question and image references. For the exact
configuration behind the measurements below, pin the earlier weights instead:
hf download h2oai/h2o-lightning-4b --revision v1.2.3 --local-dir h2o-lightning-4b (one-way only; the board's
weights are --revision v1.1).
Recommended: two-way reading, one command (one GPU, the same memory as one-way; stock vLLM 0.30.0):
bash h2o-lightning-4b/serve.sh
That starts vLLM's pooling runner on the weights with two-way attention and the shim in front of it, warms up, and
prints ready with http://127.0.0.1:8741/v1/systemone. TWO_WAY=0 bash h2o-lightning-4b/serve.sh (or
ATTENTION=one-way) is the one-way alternative: one stock generate-mode vLLM, exactly the v1.2.3 setup. What each
mode is, when to use which, and what two-way needs: Two-way reading. The two steps
behind the command, for a manual start:
1. Serve the model. Keep config.json as shipped: its "head_dtype": "float32" makes vLLM compute the logits in
fp32. Inputs over the context limit get HTTP 422. The --limit-mm-per-prompt / --mm-processor-kwargs options set
the image limits (up to 4 images per request, each scaled to at most 1,048,576 pixels inside vLLM, the cap the shim
sends with every request).
Two-way (the pooling runner; the override at both config levels, prefix caching and chunked prefill off):
vllm serve ./h2o-lightning-4b --served-model-name h2oai/h2o-lightning-4b --host 127.0.0.1 --port 8000 \
--max-model-len 40960 --gpu-memory-utilization 0.90 \
--runner pooling --convert embed --pooler-config '{"task": "embed", "seq_pooling_type": "LAST", "use_activation": false}' \
--hf-overrides '{"is_causal": false, "text_config": {"is_causal": false}}' \
--no-enable-prefix-caching --no-enable-chunked-prefill \
--limit-mm-per-prompt '{"image": 4, "video": 0}' --mm-processor-kwargs '{"max_pixels": 1048576}'
One-way (a stock generate-mode server):
vllm serve ./h2o-lightning-4b --served-model-name h2oai/h2o-lightning-4b --host 127.0.0.1 --port 8000 \
--max-model-len 40960 --gpu-memory-utilization 0.90 \
--limit-mm-per-prompt '{"image": 4, "video": 0}' --mm-processor-kwargs '{"max_pixels": 1048576}'
If vLLM stops at startup because FlashInfer cannot compile its sampling kernels (an older system CUDA toolkit), start it
with VLLM_USE_FLASHINFER_SAMPLER=0 in the environment: the decisions do not use the sampler.
2. Start the shim on the same machine, telling it which kind of server it talks to:
# two-way (the pooling runner above)
python3 h2o-lightning-4b/h2o_lightning_shim.py --config h2o-lightning-4b/serve_config.json --vllm-two-way http://127.0.0.1:8000 --port 8741
# one-way (the generate-mode server)
python3 h2o-lightning-4b/h2o_lightning_shim.py --config h2o-lightning-4b/serve_config.json --vllm http://127.0.0.1:8000 --port 8741
Run the shim as shipped for evaluations and benchmarks (including JevBench): serve_config.json is the evaluated
configuration. For production routing, see Optional: routing mode.
Before answering, the shim checks that vLLM serves h2oai/h2o-lightning-4b and that every label is one token at the
answer slot; a two-way deployment also checks the shipped label rows against the served weights and the engine's
answers to three fixed probes against the release's recorded answers; if any check fails it answers 503, so a
misconfigured server stops a run instead of scoring it. Before the first image request it also checks that vLLM's
chat template renders the same prompt as the text path.
3. Warm up until this returns HTTP 200:
curl -s http://127.0.0.1:8741/v1/systemone -H 'Content-Type: application/json' -d '{"state": "warm-up",
"questions": {"decision": {"type": "noul", "instructions": "Is this a warm-up?",
"criteria": {"true": "yes", "false": "no"}}}}'
Example requests. Against the server above (bash h2o-lightning-4b/serve.sh, or steps 1 and 2). It serves the
model as h2oai/h2o-lightning-4b (GET /v1/models); the OpenAI route also accepts h2o-lightning-4b.
The OpenAI route and the score confidences shown in this card come with the shim on main; the v1.2.3
revision pinned above serves /v1/systemone only and reports a score's confidence as the normalized maximum, so
download main (hf download h2oai/h2o-lightning-4b --local-dir h2o-lightning-4b) to use them.
The /v1/systemone API, one yes/no (noul), one choice and one score question about one record:
curl -s http://127.0.0.1:8741/v1/systemone -H 'Content-Type: application/json' -d '{
"state": {"ticket": "Checkout returns HTTP 500 for every customer since 09:12.", "plan": "enterprise"},
"questions": {
"outage": {"type": "noul", "instructions": "Is this a full outage?",
"criteria": {"true": "yes", "false": "no"}},
"team": {"type": "choice", "instructions": "Which team should take it?",
"criteria": {"payments": "Payments", "web": "Web frontend", "support": "Customer support"}},
"urgency": {"type": "score", "instructions": "How urgent is it?", "criteria": ["Low", "Medium", "High"]}}}'
The same from Python (pip install requests):
import requests
r = requests.post("http://127.0.0.1:8741/v1/systemone", json={
"state": {"ticket": "Checkout returns HTTP 500 for every customer since 09:12.", "plan": "enterprise"},
"questions": {
"outage": {"type": "noul", "instructions": "Is this a full outage?",
"criteria": {"true": "yes", "false": "no"}},
"team": {"type": "choice", "instructions": "Which team should take it?",
"criteria": {"payments": "Payments", "web": "Web frontend", "support": "Customer support"}},
"urgency": {"type": "score", "instructions": "How urgent is it?", "criteria": ["Low", "Medium", "High"]}}})
answers = r.json()["answers"]
print(answers["outage"]["noul"], answers["team"]["choice"], answers["urgency"]["score"])
# 0.801 payments 1.72... (team: payments 0.860, web 0.102, support 0.038; urgency: High 0.753)
OpenAI's Decisions API (POST /v1/decisions) with OpenAI's Python client (pip install "openai>=3.26"), pointed at
the local server: a predicate, a choice and a score question.
from openai import OpenAI
client = OpenAI(base_url="http://127.0.0.1:8741/v1", api_key="unused") # the local shim ignores the key
decision = client.decisions.create(
model="h2o-lightning-4b",
input="Ticket: checkout returns HTTP 500 for every customer since 09:12. Plan: enterprise.",
questions=[
{"type": "predicate", "name": "outage", "instructions": "Is this a full outage?"},
{"type": "choice", "name": "team", "instructions": "Which team should take it?",
"choices": [{"value": "payments", "description": "Payments"}, {"value": "web", "description": "Web frontend"},
{"value": "support", "description": "Customer support"}]},
{"type": "score", "name": "urgency", "instructions": "How urgent is it?",
"levels": [{"label": "Low"}, {"label": "Medium"}, {"label": "High"}]},
],
)
print(decision.model_dump_json(indent=1))
Each answer comes back in OpenAI's shape (rounded): {"type": "predicate", "name": "outage", "probability": 0.801},
{"type": "choice", "name": "team", "choice": "payments", "confidence": 0.839, "probabilities": [{"value": "payments", "probability": 0.892}, ...]}, {"type": "score", "name": "urgency", "score": 1.752, "confidence": 0.775, "probabilities": [{"label": "Low", "value": 0, "probability": 0.022}, ...]}. The OpenAI route asks the model through the same
decision as /v1/systemone, in the same option format: a choice's value is the option and its description the
option's text, a score level is its label, and a predicate is a yes/no question with the default wording ("the
statement holds" / "it does not"). Its numbers differ from the call above because the input is a sentence rather than
the same record and the predicate has no yes/no descriptions.
The outage probability is 0.801 on both routes because yes/no answers are reported at no
less than 0.801 on their chosen side. A choice's confidence is the normalized maximum (0 for
a uniform answer, 1 for a certain one); a score's is the probability of its most likely level. An image goes in an
input message as {"type": "input_image", "image_url": "data:image/png;base64,..."} next to
{"type": "input_text", "text": ...}.
4. Run JevBench's harness:
cd <JEVBENCH> && python3 -m jevbench.cli run \
--tasks datasets/public/easy.jsonl,datasets/public/original.jsonl,datasets/public/hard.jsonl \
--adapter typesafe --endpoint http://127.0.0.1:8741 --key-env '' --model h2oai/h2o-lightning-4b \
--cost-basis self_hosted_gpu --reserve-usd 0 --results <OUT>/results.jsonl --raw-dir <OUT>/raw \
--ledger <OUT>/ledger.jsonl --manifest <OUT>/manifest.json --run-label h2o-lightning-4b --delay-s 0
The API. Send requests to POST /v1/systemone. One request can carry several questions about the same state:
{"state": "Ticket 4471: since 09:10 the checkout page returns HTTP 500 for every customer; no orders have gone through in 40 minutes. Severity guide: P1 = a revenue path fully down; P2 = degraded but working; P3 = cosmetic.",
"questions": {
"priority": {"type": "choice", "instructions": "Which priority does the severity guide assign?",
"criteria": {"p1": "Revenue path fully down", "p2": "Degraded but working", "p3": "Cosmetic"}},
"all_users": {"type": "noul", "instructions": "The problem affects every customer.",
"criteria": {"true": "Affects everyone", "false": "Affects only some"}},
"urgency": {"type": "score", "instructions": "How urgent is this ticket?", "criteria": ["Low", "Medium", "High"]}}}
The response (rounded here):
{"model": "h2oai/h2o-lightning-4b",
"answers": {"priority": {"type": "choice", "choice": "p1",
"probabilities": {"p1": 0.956, "p2": 0.032, "p3": 0.013}, "confidence": 0.934},
"all_users": {"type": "noul", "noul": 0.928},
"urgency": {"type": "score", "score": 1.864, "legend": {"0": "Low", "1": "Medium", "2": "High"},
"probabilities": {"0": 0.016, "1": 0.104, "2": 0.880}, "confidence": 0.880}},
"probability_source": "native", "effort_used": {"tier": "fast", "passes_per_decision": 1},
"usage": {"input_tokens": 231, "processed_input_tokens": 231, "output_tokens": 3, "latency_ms": 62.0}}
usage.input_tokens counts the prompt head that the questions share once; usage.output_tokens is one label
token read per answered question. A record over the state limit (max_state_tokens) is cut for reading, but
usage.input_tokens still counts it whole; usage.processed_input_tokens is what vLLM read.
Images. Put each image in the request as a data:image/...;base64,... URI. It can go anywhere inside state (as a
string, an object value or a list item), or in a top-level images list next to state and questions. The images
list also takes bare base64 strings and https image links (the shim fetches a link itself, from public addresses
only and with size and time limits, and does not store it; the server needs network access for those, and a link it
cannot fetch gets HTTP 422). Chat-style parts ({"type": "image_url", "image_url": {"url": ...}}) and multipart/form-data (the JSON in a
request field, each image as a file part) work too.
state leaves [image N] in its place, so the record can refer to it. Images in the
top-level list are numbered first.https on port 443 (plain http needs LIGHTNING_IMAGE_URL_ALLOW_HTTP=true), an image/* answer with HTTP 200 after at most 3 redirects, 5 s and 20 MB per link (LIGHTNING_IMAGE_FETCH_SECONDS, LIGHTNING_IMAGE_FETCH_MAX_BYTES); LIGHTNING_IMAGE_URLS=off refuses links.serve_config.json,
"image"); text answers use per-type temperatures (serve_config.json).This example uses example_receipt.png from this repository:
import base64, json, urllib.request
img = base64.b64encode(open("h2o-lightning-4b/example_receipt.png", "rb").read()).decode()
req = {"state": {"receipt": "data:image/png;base64," + img,
"claim": {"employee": "J. Ortiz", "category": "office supplies", "amount": "444.26"}},
"questions": {
"matches": {"type": "noul", "instructions": "The receipt total equals claim.amount.",
"criteria": {"true": "Same amount", "false": "Different amount"}},
"items": {"type": "choice", "instructions": "How many item lines are on the receipt?",
"criteria": {"three": "3", "four": "4", "five": "5", "six": "6"}},
"legible": {"type": "score", "instructions": "How legible is the receipt?",
"criteria": ["Unreadable", "Partly readable", "Fully readable"]}}}
r = urllib.request.urlopen(urllib.request.Request("http://127.0.0.1:8741/v1/systemone", json.dumps(req).encode(),
{"Content-Type": "application/json"}))
print(json.dumps(json.load(r), indent=1))
The response (rounded here):
{"model": "h2oai/h2o-lightning-4b",
"answers": {"matches": {"type": "noul", "noul": 0.964},
"items": {"type": "choice", "choice": "six",
"probabilities": {"three": 0.006, "four": 0.012, "five": 0.024, "six": 0.958}, "confidence": 0.943},
"legible": {"type": "score", "score": 1.926,
"legend": {"0": "Unreadable", "1": "Partly readable", "2": "Fully readable"},
"probabilities": {"0": 0.011, "1": 0.052, "2": 0.937}, "confidence": 0.937}},
"probability_source": "native", "effort_used": {"tier": "fast", "passes_per_decision": 1},
"usage": {"input_tokens": 585, "processed_input_tokens": 585, "output_tokens": 3, "latency_ms": 141.0, "images": 1}}
usage.input_tokens includes the image tokens; usage.images counts the images read.
Status codes. An input the shim cannot take gets HTTP 422, which the runner scores as one wrong answer. That covers:
An empty request gets 400. vLLM's 401, 403 and 429 pass through. Any other vLLM failure is a 502, which counts toward the runner's three-consecutive-failures stop.
Tests (no GPU): python3 h2o-lightning-4b/test_shim.py and python3 h2o-lightning-4b/test_security.py.
What it is. A decoder reads a prompt one way: each token attends only to what comes before it, and the answer is read at the last position. Since v1.3 the weights are trained to answer under two patterns: one-way (causal, as every text generator and stock vLLM read a prompt) and two-way: bidirectional attention on the model's full-attention layers, so the answer position sees the record, the question and the options in both directions before the readout (the Gated DeltaNet layers, the model's linear-attention layers, stay causal). It is one forward pass and one readout in both modes, and the same shim, request format and calibration.
Why both. Two-way reads a little better: on the Decision Index 0.3 public suite +1.2 on text (57.10 against
55.88) and +0.4 on vision (68.00 against 67.57), and 202 against 198 on JevBench's 231 public items (all measured
above). One-way needs nothing beyond stock vLLM's generate mode, works with prefix caching, and serves Box questions
(a generation) from the same engine; it is the mode of every earlier release. The weights were trained to handle
both, so a deployment can pick either, and a client can ask per request when both engines run (the Box pair,
LIGHTNING_BOX_ENABLED=1); the default single engine answers two-way and gives HTTP 400 to a one-way request.
When to use which. Two-way (the default) for decisions, text or images, on one GPU: the recommended choice. One-way when you need Box questions without a second engine, when many questions share one long record and you want the prefix cache, when you want the exact v1.2.3 behaviour, or on a server you cannot start in pooling mode.
How two-way is served. vLLM's pooling runner, started with the override
{"is_causal": false, "text_config": {"is_causal": false}} (the nested entry is the one the layers read; the outer
one turns chunked prefill and prefix caching off, which two-way prompts must not have; serve.sh sets both and the
two flags explicitly), returns the model's final hidden state at the answer slot instead of generating. The shim
multiplies that state with the lm_head rows of the 255 option labels shipped in label_rows.safetensors
(pooled_readout.py, standard library) and reads every option exactly as the one-way path reads it from vLLM's
logprob_token_ids. Requirements: vLLM 0.30.0 (stock; no patch), the model folder from main
(label_rows.safetensors beside serve_config.json), one GPU with the memory one-way needs (measured on a 48 GB L40S
at --gpu-memory-utilization 0.90; 9.3 GB of weights), --max-model-len 40960 as shipped. The first two-way
request also hashes model.safetensors once (the identity check below; about a minute on a slow disk; serve.sh's
warm-up waits for it). The pooling runner has no
prefix cache, so a multi-question decision computes each question's whole prompt: usage.processed_input_tokens
reports what was read; usage.input_tokens is the same count as one-way (the shared record once). The two-way
calibration (serve_config.json two_way.temperature, two_way.noul_floor, two_way.image_temperature) ships
with the one-way values, the ones every number above was measured with; a missing value falls back to the one-way one
with a warning when the engine is first checked.
Launching each mode.
bash h2o-lightning-4b/serve.sh # two-way (default): one pooling-runner vLLM + the shim
TWO_WAY=0 bash h2o-lightning-4b/serve.sh # one-way: one stock generate-mode vLLM + the shim
LIGHTNING_BOX_ENABLED=1 bash h2o-lightning-4b/serve.sh # two-way + Box: adds a generate-mode vLLM for Box
With TWO_WAY=1 the shim is started with --vllm-two-way; every request is read two-way; a request asking for
"attention_mode": "causal" gets HTTP 400 (there is no one-way engine), never a silent two-way answer, and every
response states the mode it was read in ("attention_mode"). Box questions are a generation, which the pooling
runner cannot do: with LIGHTNING_BOX_ENABLED=1, serve.sh starts a second, generate-mode vLLM on port 8001 after
the two-way engine is up, if the GPU has BOX_ENGINE_MIB (default 14,000 MiB) free; with LIGHTNING_BOX_ENABLED=1
both engines are started at --gpu-memory-utilization 0.45 (two copies of the weights and two caches; measured on a
48 GB L40S; set GPU_UTIL to change it), Box questions run on the
generate engine, and a request may choose either mode ("attention_mode": "causal" or "bidirectional", also
"one-way" / "two-way"; without it, two-way). If there is no room, or that engine fails to start, decisions keep
serving two-way and a box question gets a clear HTTP 400 (the alternative is TWO_WAY=0, one-way with Box on one
engine). The /v1/decisions route takes the same attention_mode field.
curl -s http://127.0.0.1:8741/v1/systemone -H 'Content-Type: application/json' -d '{
"state": {"ticket": "Checkout returns HTTP 500 for every customer since 09:12.", "plan": "enterprise"},
"questions": {"outage": {"type": "noul", "instructions": "Is this a full outage?",
"criteria": {"true": "yes", "false": "no"}}}}'
The start-up guard. Before its first two-way answer the shim checks that the engine serves the model, that
label_rows.safetensors belongs to the served model.safetensors (its sha256, hashed once and kept in
.model_sha256.json beside the weights) and holds this model's label tokens, that the pooled state is not normalised,
and that the engine's answers to three fixed probes are within 0.05 of the answers recorded on the release weights
(serve_config.json two_way.probe_reference): an engine on other weights or another dtype, or started without the
override (it would read one-way and answer plausibly; in our check such an engine differed from the recorded two-way
answers by 0.11 and from the one-way engine by 0.004), is refused with HTTP 503 and the reason, checked again after
10 s (SHIM_TWO_WAY_RETRY_SECONDS). With the Box pair up, the two engines must also differ on the probes.
Reference implementation. For Qwen3.5 the nested override on stock vLLM 0.30.0 is the whole mechanism. Our vLLM
branch, h2oai/vllm, branch h2o/gemma4-noncausal-full-attention
(commit 88cd4a0d82), is the reference implementation of the same two-way reading: it adds a noncausal_full_attention
config declaration that reaches the attention layers of both Qwen3.5 and Gemma-4 (stock vLLM ignores a flat override
on a multimodal folder, which is why the entry above is nested), encoder-only attention for Gemma-4's full-attention
layers (including the E4B's KV-shared layers), a guard that refuses an engine whose declared layers are still causal,
and parity tests against the transformers reference. Use stock vLLM for this model; use the branch to read how it
works or to serve a Gemma-4-based model two-way.
Images can be sent by reference: put each image once under "assets"
({"<ref>": {"type": "image", "format": "png", "data_base64": "..."}}, "jpg" for JPEG) and write <ref> wherever
the image belongs in state; the shim replaces the reference with the image. References match as plain text, so
every occurrence counts, even inside a longer word (photo also matches "a photo of"); each distinct reference is
sent to the model once, and every occurrence points at that image. Pick references that cannot occur in your text,
such as IMG_1. PNG and JPEG only, 16 MiB per file,
every asset referenced at least once, no URL fetching; a malformed asset map is a 400.
A box question, {"type": "box", "instructions": "the coffee mug in `photo`"}, answers with a bounding box
{"left", "top", "right", "bottom"} in fractions of the image, confidence (the probability that the box tightly
contains the target), present (the probability that the target is in the image) and found (whether a box was
located; if not, the box is the whole image with confidence 0). Box is off by default: a box question gets 400 until
serve_config.json sets "box": {"enabled": true, ...} (or LIGHTNING_BOX_ENABLED=1). box.mode chooses how the box is found: "generate" (the default: one constrained generation of the box),
"edges" (each edge read as a distribution over positions, the coordinate its expected value) or "hybrid" (both,
the tighter box answered). edges and hybrid need a model trained on edge readouts; keep generate with this
release.
Measured with the one-way (generate-mode) engine on the v1.2.3 weights; the pooling runner behind the two-way
default has no prefix cache and was not measured at scale. VLLM_ARGS reaches both engines with serve.sh.
Why a stock server stalls. Qwen3.5 interleaves 24 Gated DeltaNet (linear-attention) layers with 8 full-attention layers. With prefix caching on, vLLM 0.30.0 keeps their recurrent state only at 528-token block boundaries (272 with the bfloat16 state below), and its scheduler defers a request whose cached prefix ends on a state block written in the same step, then stops scanning the waiting queue. The shim sends a decision's questions together over one shared record, so under load the engine runs about one decision per scheduler step, however many are waiting. Zeroing the state of new sequences also synchronises the GPU in each linear-attention layer in every step that starts new sequences.
Two patches fix it, in vllm_patches/ (sha256 in vllm_patches/SHA256SUMS; vLLM 0.30.0 only):
vllm030_scheduler_skip_same_step_mamba.patch skips the deferred request for that step instead of ending the scan
(scheduling only), and vllm030_gdn_initial_state_no_sync.patch zeroes those states with torch.where (no GPU sync,
identical values). In our test, both patches together gave the same outputs as stock vLLM 0.30.0 (687
development-set decisions with known answers identical; largest change in the raw label probabilities of 231 questions:
0.000). Patch A changes only which requests share a step, so under load results can differ by ordinary BF16 batching
noise, as they do on stock vLLM. If you pinned --revision v1.2.3, download main for vllm_patches/ and the current serve.sh. VLLM_PATCHES=1 bash h2o-lightning-4b/serve.sh applies them to the vLLM
in the active environment before starting it; it edits that install, so use a dedicated virtual environment. Without
VLLM_PATCHES=1, serve.sh runs stock vLLM.
Recommended flags for many decisions in flight: --max-cudagraph-capture-size 2048 (measured below). We also set
--max-num-batched-tokens 8192; it was not set in the runs below. Optional: --mamba-ssm-cache-dtype bfloat16 (about
3 % more throughput; no answer changed on the 687 decisions, largest probability change 0.022) and --quantization fp8 (below). With serve.sh, pass them in VLLM_ARGS, for example
VLLM_PATCHES=1 VLLM_ARGS="--max-cudagraph-capture-size 2048 --max-num-batched-tokens 8192" bash h2o-lightning-4b/serve.sh.
One H100 80GB, one vLLM engine (--gpu-memory-utilization 0.85), each decision three questions sent concurrently over a
fresh record (each question prompt about 740 tokens), the shim's request pattern, but sent straight to vLLM rather than
through the shim (decisions per second, median latency). Through the shim, raise SHIM_QUESTION_THREADS (default 64)
to at least three times the decisions in flight.
| vLLM 0.30.0 | 1 in flight | 16 in flight | 64 in flight |
|---|---|---|---|
| stock | 13.3/s, 74 ms | 29.0/s, 551 ms | 29.0/s, 2,252 ms |
patched, BF16, --max-cudagraph-capture-size 2048 |
16.4/s, 61 ms | 79.0/s, 203 ms | 81.6/s, 766 ms |
patched, FP8, --max-cudagraph-capture-size 2048 |
18.6/s, 53 ms | 91.3/s, 176 ms | 99.2/s, 631 ms |
Answers. The patches changed no answer in our test. The larger CUDA-graph capture size only adds BF16 batching
noise (1 of the 687 answers changed, a near-tie; largest probability change 0.019). FP8 changes about 3 % of answers
(21 of the 687), almost all near-ties (19 where the top two options were within 0.1 of each other); the accuracy
difference is not significant (FP8 got 3 fewer right, McNemar p = 0.63). The calibration temperatures in
serve_config.json were fitted on BF16 output, not re-fitted for FP8: FP8 runs use them as they are for now.
SGLang 0.5.21's multi-item scoring API (/v1/score) was faster than patched vLLM only at saturation (90.7 vs 81.6
decisions/s at 64 in flight, both BF16), was slower at 1-16 in flight, and shifts answers (97.8 % of raw label argmaxes
agree with vLLM).
Not for benchmark or leaderboard runs. Those use the shipped serve_config.json unchanged.
As shipped, the shim reports each yes/no answer at no less than 0.801 on its chosen side ("noul_floor": 0.801 in
serve_config.json). That is the evaluated configuration, and it is why no shipped yes/no answer falls between 0.2 and
0.8. If you put the model in front of a fallback, and escalate uncertain answers to a larger model or a person, you
usually want the raw yes/no probability instead, so uncertain yes/no answers can be flagged. In that deployment only,
start the shim with the floor off:
SHIM_NOUL_FLOOR=0 python3 h2o-lightning-4b/h2o_lightning_shim.py --config h2o-lightning-4b/serve_config.json --vllm http://127.0.0.1:8000 --port 8741
The same SHIM_NOUL_FLOOR / SHIM_TEMPERATURE overrides apply to a two-way deployment (--vllm-two-way, or
SHIM_NOUL_FLOOR=0 bash h2o-lightning-4b/serve.sh): they set both modes' values.
The floor never changes which answer is chosen, and choice and score answers are unaffected. See Routing thresholds for what each threshold escalates with the floor off.
adapter/ holds H2O-Lightning-4B's decision adapter as a LoRA for the base model
Qwen/Qwen3.5-4B. Serve the base model with the adapter on vLLM, and one
server answers both kinds of request:
model: "h2oai/h2o-lightning-4b" (the adapter), through the same shim and readout as the
merged model;model: "Qwen/Qwen3.5-4B" (the base model, no adapter).On JevBench's 231 public items (v1.2.3 weights and their adapter), the adapter scored the same as the merged model
(205/231) and gave the same top answer on 230 of 231 items. adapter/ on main is the v1.3 adapter, the one the v1.3
weights were merged from; its hybrid-mode score is not measured separately (pin --revision v1.2.3 on the download
below for the measured pair). Measured on one RTX A6000: 94 ms per decision (p50, versus 60 ms for the merged model);
about 1.3 s for a 90-token reply from the base model.
0. Get the adapter into the same folder as the download above (shim and serve_config.json included):
hf download h2oai/h2o-lightning-4b --include "adapter/*" --local-dir h2o-lightning-4b && cd h2o-lightning-4b
1. Serve the base model with the adapter (vLLM 0.30.0, from the folder that contains adapter/):
VLLM_USE_FLASHINFER_SAMPLER=0 vllm serve Qwen/Qwen3.5-4B --revision 851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a --host 127.0.0.1 --port 8000 \
--max-model-len 40960 --gpu-memory-utilization 0.90 --max-num-seqs 64 \
--enable-lora --max-lora-rank 64 --max-loras 1 --lora-modules h2oai/h2o-lightning-4b=./adapter \
--limit-mm-per-prompt '{"image": 4, "video": 0}' --mm-processor-kwargs '{"max_pixels": 1048576}'
--max-num-seqs: Qwen3.5's linear-attention layers need one state block per running sequence, so keep this at or
below what fits. vLLM stops at startup with a clear message if it's too high.VLLM_USE_FLASHINFER_SAMPLER=0 is needed only where FlashInfer can't compile its sampler (an older CUDA toolkit).
The decisions don't use the sampler.2. Put the shim in front for decisions. Use the same shim and config as the merged model. The LoRA's name is the served model name the shim expects:
python3 h2o_lightning_shim.py --config serve_config.json --vllm http://127.0.0.1:8000 --port 8741
Decisions then go to POST http://127.0.0.1:8741/v1/systemone exactly as described above.
3. Text from the base model on the same server:
curl -s http://127.0.0.1:8000/v1/chat/completions -H 'Content-Type: application/json' -d '{"model": "Qwen/Qwen3.5-4B",
"messages": [{"role": "user", "content": "Write a two-sentence status update for customers about a checkout outage that is now fixed."}],
"max_tokens": 200, "chat_template_kwargs": {"enable_thinking": false}}'
Check that the adapter is active. The two lines must differ; if they are identical, vLLM is serving the base model under the adapter's name:
for m in Qwen/Qwen3.5-4B h2oai/h2o-lightning-4b; do curl -s http://127.0.0.1:8000/v1/completions -H 'Content-Type: application/json' -d "{\"model\": \"$m\", \"prompt\": \"Ticket: checkout is down for every customer. Priority (P1, P2 or P3):\", \"max_tokens\": 1, \"temperature\": 0, \"logprobs\": 5}" | python3 -c "import json,sys; print(sys.argv[1], json.load(sys.stdin)['choices'][0]['logprobs']['top_logprobs'][0])" "$m"; done
Must-rename note for converted or re-exported adapters. vLLM loads Qwen3.5-4B as
Qwen3_5ForConditionalGeneration, so the adapter's tensor names must bebase_model.model.model.language_model.layers.N.…. The file shipped here already uses those names. An adapter saved from a text-only load of the model (base_model.model.model.layers.N.…) is accepted by vLLM without any warning and changes nothing: the output equals the base model. Rename the keys (insertlanguage_model.aftermodel.model.) and run the check above.
The adapter's own scaling is the standard lora_alpha / r. Use it as is, with no extra scale.
H2O-Lightning-4B was fine-tuned from Qwen3.5-4B in three stages. Every training example is a record (a document, ticket, policy, conversation, game state...) with one typed question about it and a graded answer. The first stage is broad, the second concentrates on reading long documents and on numbers, dates and probabilities, and the last stage mixes everything back in with more support, everyday-language, safety and coding cases.

| Use case | Stage 1: broad | Stage 2: focused | Stage 3: final | All stages |
|---|---|---|---|---|
| Documents, policies & rules (contracts, policies, multi-step reading, judging answers) | 34% | 49% | 36% | 37% |
| Numbers, dates & probability | 24% | 41% | 15% | 22% |
| Games & simulations (state tracking, planning, control) | 23% | 2% | 6% | 12% |
| Everyday language & knowledge | 8% | 1% | 15% | 10% |
| Support & operations (tickets, routing, workflows) | 6% | 4% | 16% | 10% |
| Safety & guardrails | 6% | 3% | 9% | 7% |
| Coding & tool calls | - | - | 3% | 2% |
| Finance & commerce | - | - | 1% | 0.5% |
Use cases are assigned per data family, so the split is approximate.
Question types. About half of the examples are choice questions, with yes/no and score questions making up the rest. Yes/no and score questions get a bigger share in the final stage.

| Question type | Stage 1 | Stage 2 | Stage 3 | All stages |
|---|---|---|---|---|
| Choice | 62% | 62% | 46% | 54% |
| Yes / no | 23% | 29% | 34% | 29% |
| Score | 14% | 9% | 20% | 16% |
Text and images. All fine-tuning examples were text, and almost all (over 99%) were in English. The model reads images with Qwen3.5-4B's vision encoder, which fine-tuning did not change.
The weights also run outside vLLM. The builds and measurements in this section are the v1.2.x weights, one-way (the v1.3 weights and two-way reading are not yet built for these runtimes):
/v1/systemone) straight from llama-server
with the H2O-Lightning decision support proposed in llama.cpp pull request #30361;
its card explains how to build that until the pull request is merged. For standard llama.cpp, the same repo has
stock files and a shim that serves the same API, with a one-command launcher.We converted these weights with mlx-vlm at four precisions and ran them on the GPU of an Apple M4 (24 GB), reading answers with the same readout as this repo's shim. On 793 held-out decision questions, compared with the same model served by vLLM:
| Runtime | Size (GB) | Same answer as vLLM | Accuracy change (95% CI) | Calibration error (ECE) | Brier score |
|---|---|---|---|---|---|
| vLLM, BF16 (reference) | 0.033 | 0.242 | |||
| MLX, BF16 | 9.10 | 99.5 % | +0.1 pts (−0.3 to +0.5) | 0.033 | 0.242 |
| MLX, 8-bit | 5.16 | 99.0 % | −0.1 pts (−0.8 to +0.5) | 0.034 | 0.242 |
| MLX, 4-bit mixed | 3.37 | 92.3 % | −0.4 pts (−2.1 to +1.4) | 0.029 | 0.252 |
| MLX, 4-bit | 3.06 | 91.3 % | −0.4 pts (−2.3 to +1.4) | 0.041 | 0.254 |
BF16 and 8-bit agree with vLLM on 99 % or more of answers, with the same calibration. The 4-bit builds show no accuracy change we can detect on this sample, but they change about 1 answer in 12 and their probabilities are a little less accurate (Brier about 0.01 higher). The mixed build keeps the token embedding (shared with the output head) and some projections at 6 or 8 bits. ECE and Brier (lower is better) are measured on the 679 of these questions from public third-party sets. Sizes include the vision encoder, kept at BF16. We have not published this MLX conversion; the community builds above are separate files and were not measured here.
usage.input_tokens.Apache-2.0. Built on Qwen/Qwen3.5-4B by the Qwen team (Alibaba Cloud), Apache-2.0; served with unmodified vLLM (Apache-2.0).
Base model
Qwen/Qwen3.5-4B-Base
Install from pip and serve model
# Install vLLM from pip: pip install vllm# Start the vLLM server: vllm serve "h2oai/h2o-lightning-4b"# Call the server using curl (OpenAI-compatible API): curl -X POST "http://localhost:8000/v1/chat/completions" \ -H "Content-Type: application/json" \ --data '{ "model": "h2oai/h2o-lightning-4b", "messages": [ { "role": "user", "content": [ { "type": "text", "text": "Describe this image in one sentence." }, { "type": "image_url", "image_url": { "url": "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg" } } ] } ] }'