

Accelerate Bench: Evaluating Agents for Application-Level Program Optimization
Paper • 2611.20882 • Published • 20
Read the access commitments and privacy notice on the dataset card, then describe your intended evaluation. / 请先阅读数据集页面上的访问承诺与隐私说明,再描述计划开展的评测。
Access is for evaluation. Do not use the requested controlled evaluation assets for pretraining, fine-tuning, distillation or reinforcement-learning training, and do not publicly redistribute them. Normal model evaluation is allowed. These commitments do not relicense source code or tools. The full access commitments and privacy notice are on the dataset card. / 访问用于评测:不将本次申请的受控评测资产用于预训练、微调、蒸馏或强化学习训练,不公开再分发;允许正常模型评测。这些承诺不重新许可源码或工具。完整的访问承诺与隐私说明见数据集页面。
Log in or Sign Up to review the conditions and access this dataset content.
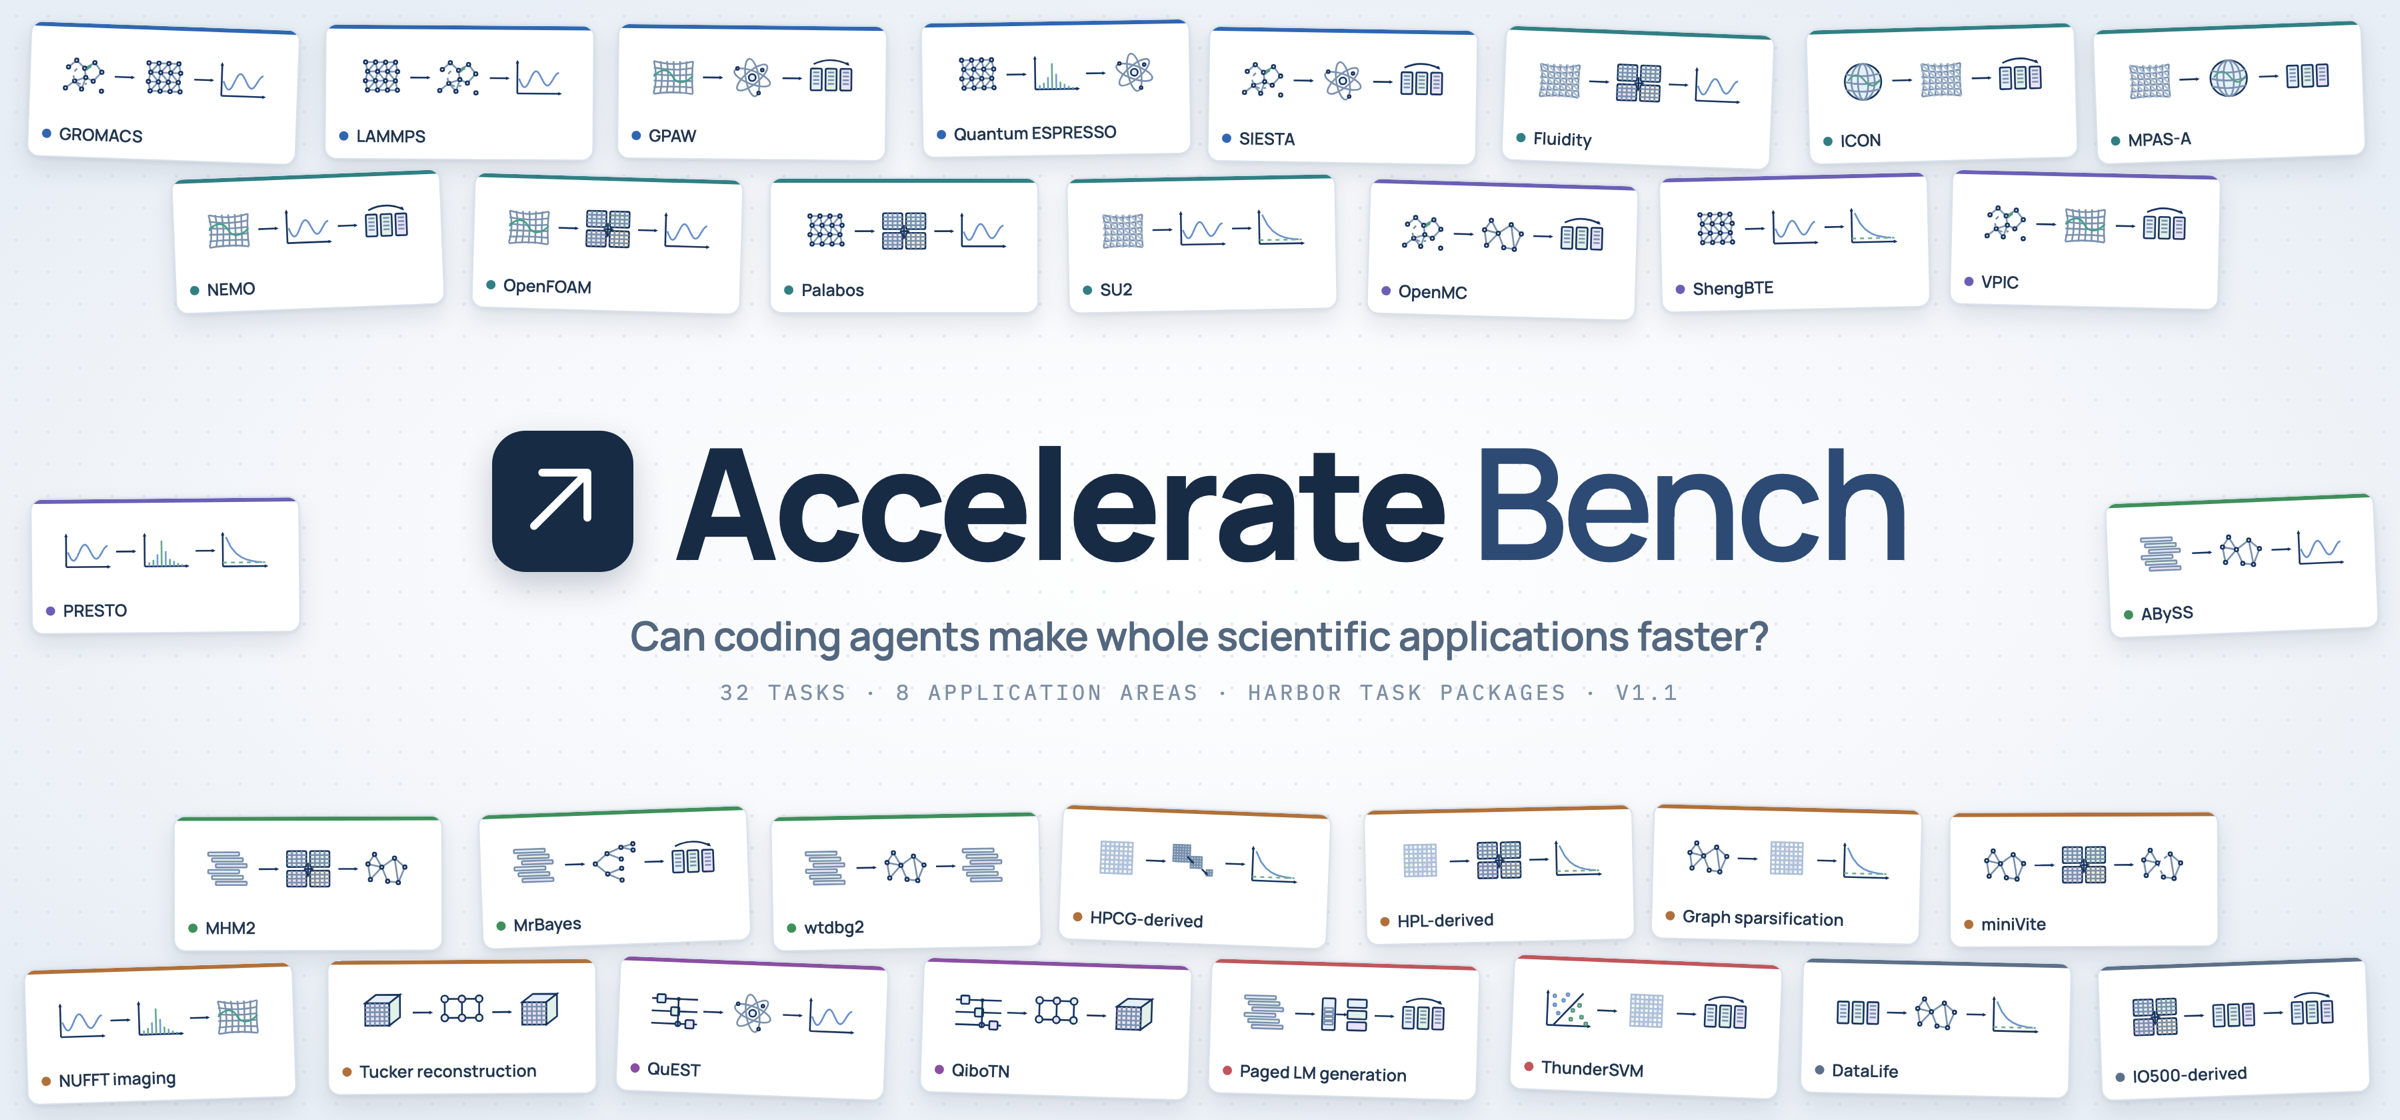
Accelerate Bench asks whether coding agents can make whole scientific applications faster without breaking them. This dataset holds the 32 tasks of v1.1, the version evaluated in the paper, as Harbor task packages.
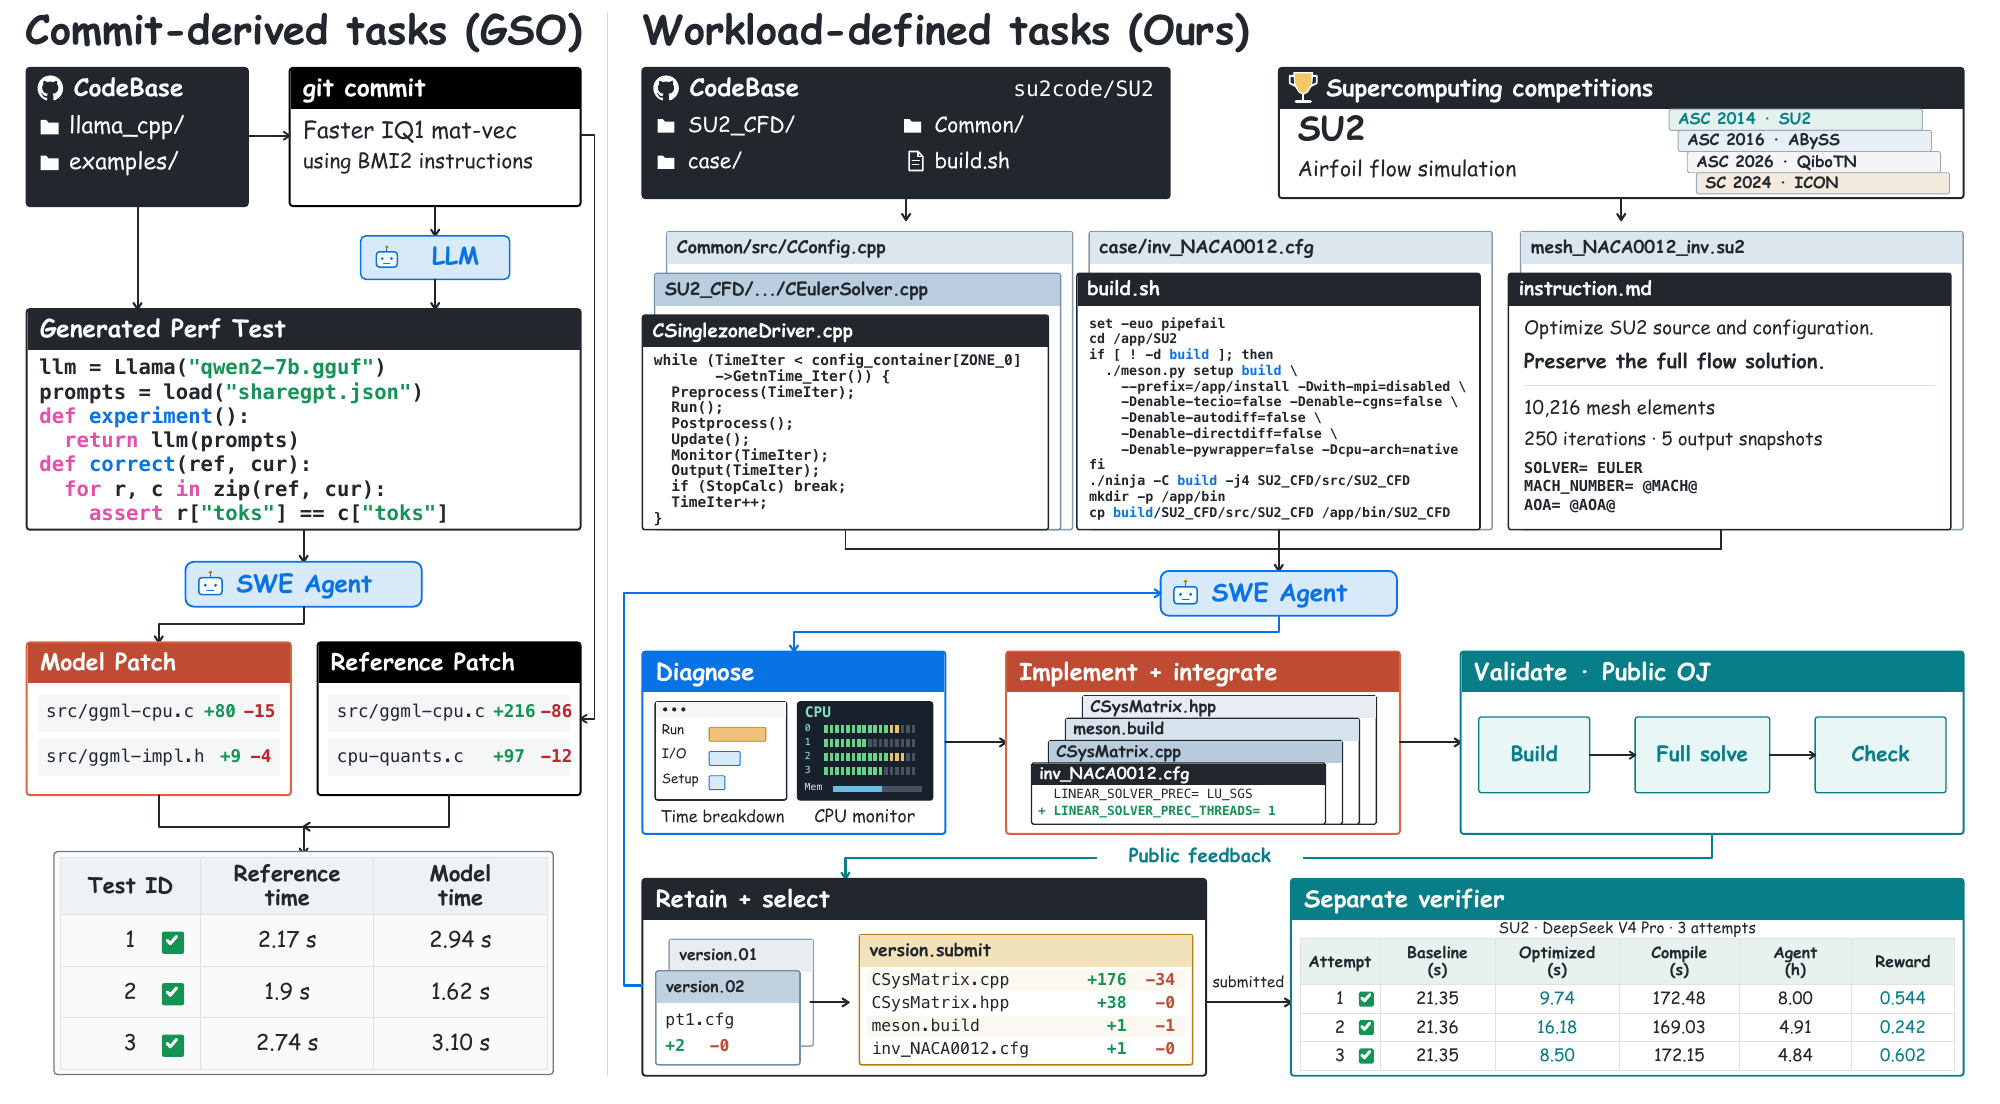
Commit-derived tasks (left, as in GSO) start from one known performance commit and measure the agent's patch against it. Accelerate Bench tasks (right) fix the workload and the computation that must be preserved; the agent decides where and how to optimize, and a separate verifier scores the final program.
Each task gives a coding agent a working scientific application, a fixed workload and a CPU and memory budget. The agent has eight hours to make the whole program faster while every required output stays correct; a separate private verifier then rebuilds the final program, checks it on hidden inputs and times it against the unmodified program.
task.toml, instruction.md, environment/ and tests/accelerate-bench-v1.1-harbor-tasks.tar.gz, 2.56 GBaccelerate-bench/accelerate-benchTo run the tasks without a request, use Harbor Hub; it has every task except ICON.
The full archive in this repository has all 32 tasks and a manifest of every file's SHA-256. Request access with the form above: give your institution (or “Independent”) and your planned evaluation. Approval is manual. Model evaluation, reproduction, auditing and teaching are supported. Please do not use the tasks for pretraining, fine-tuning, distillation or reinforcement-learning training, and do not redistribute the archive publicly.
Access requests support benchmark evaluation, reproduction, auditing and teaching; normal evaluation of models is allowed. Please provide your institution or organization (“Independent” if unaffiliated), a purpose category and a short description of the intended evaluation, without confidential project details or sensitive personal information. Hugging Face provides the account information used for the request.
For the controlled evaluation assets requested through this repository, you confirm that you will not use them for model pretraining, fine-tuning, distillation or reinforcement-learning training, and that you will not publicly redistribute them.
These are access-use commitments for controlled evaluation assets. They do not relicense source code or tools, remove rights granted by existing component licenses, or add a commercial-use restriction. Original author-owned code and tools remain Apache-2.0; third-party components keep their licenses. The manuscript's CC BY 4.0 license is separate.
Requests are reviewed by Bowen Liu, the maintainer of this repository (bliu690@connect.hkust-gz.edu.cn). Applications are managed in Hugging Face; the account information and form answers are used only to review requests, manage access and contact applicants about them. They are not published in the repository, the dataset, benchmark outputs, the paper, the leaderboard or public logs, and no offline bulk exports are made.
The form asks only for an institution, a purpose category, a short evaluation description and two confirmations. Do not provide passwords, tokens, identity documents, billing details or confidential project information. Contact the maintainer to correct or delete any maintainer-held copies; Hugging Face's own records follow its policies.
Harbor downloads the 31 public tasks itself. It needs Linux x86-64 with Docker:
pip install harbor==0.22.0
export ANTHROPIC_API_KEY=...
harbor run -d accelerate-bench/accelerate-bench@v1.1 \
  -a claude-code -m anthropic/MODEL_ID --ak reasoning_effort=high -n 1
-n 1 runs one task at a time. Each task gives the agent 4 or 8 CPUs and up to 32 GiB of memory and runs a public-test service next to it, so raise -n only if the host has room for several tasks at once. Add -i hpcg-multigrid-pcg to run a single task. ICON is not on Harbor Hub because its two grid files have to be downloaded from their official source.
After approval, the recommended route is the downloader in the code repository, which checks the archive and every task file before installing them into canonical/tasks/:
git clone https://github.com/AdAstraAbyssoque/accelerate-bench
cd accelerate-bench
pip install -r requirements-download.txt
hf auth login
python scripts/download_data.py
To download the archive directly instead:
hf download AdAstraAbyssoque/accelerate-bench \
  accelerate-bench-v1.1-harbor-tasks.tar.gz SHA256SUMS \
  --repo-type dataset --revision 9b7825dbee991573edbc290f6effaffbffff8d7e \
  --local-dir ./accelerate-bench-data
cd accelerate-bench-data
sha256sum -c SHA256SUMS        # macOS: shasum -a 256 -c SHA256SUMS
tar -xzf accelerate-bench-v1.1-harbor-tasks.tar.gz
ICON's two grid files are downloaded from their official source; the quickstart has the command and shows how to run a task with Harbor.
Benchmark v1.1, one run per agent and task, with all final programs scored on the same machine (paper Table 1). Score@1 and Aτ are percentages.
| # | Agent | Harness | Score@1 | GM | A1.25 | A2 |
|---|---|---|---|---|---|---|
| 1 | Claude Sonnet 5.5 | Claude Code | 67.4 | 3.83× | 100.0 | 71.9 |
| 2 | Claude Opus 5.5† | Claude Code | 59.4 | 3.94× | 84.4 | 68.8 |
| 3 | GPT-6.1 Sol | Codex | 49.2 | 2.42× | 78.1 | 50.0 |
| 4 | GPT-6 Astra | Codex | 47.2 | 2.40× | 75.0 | 53.1 |
| 5 | Hy4-Preview | Claude Code | 45.2 | 2.31× | 71.9 | 50.0 |
| 6 | Hy4 | Claude Code | 45.0 | 2.41× | 75.0 | 46.9 |
| 7 | Kimi K3 | Claude Code | 42.5 | 2.47× | 68.8 | 40.6 |
| 8 | DeepSeek-V4.1-Flash-1017 | Claude Code | 40.1 | 2.28× | 65.6 | 34.4 |
| 9 | GLM-5.3 | Claude Code | 39.7 | 2.20× | 65.6 | 40.6 |
| 10 | GLM-5.3-Flash | Claude Code | 39.3 | 2.20× | 68.8 | 34.4 |
| 11 | DeepSeek-V4-Pro | Claude Code | 37.9 | 2.19× | 62.5 | 34.4 |
| 12 | GPT-6.1 Terra | Codex | 37.9 | 1.92× | 75.0 | 25.0 |
| 13 | DeepSeek-V4-Flash | Claude Code | 34.1 | 1.92× | 56.2 | 34.4 |
| 14 | GLM-5.2 | Claude Code | 34.0 | 1.98× | 46.9 | 37.5 |
| 15 | Grok 4.6 | Claude Code | 33.9 | 2.13× | 50.0 | 34.4 |
| 16 | Hy3 | Claude Code | 25.5 | 1.76× | 37.5 | 28.1 |
†The provider's safety system stopped the Claude Opus 5.5 runs on Graph sparsification, PRESTO and VPIC; they count as failures with zero reward. On its other 29 tasks, Claude Opus 5.5 scores 65.6%. Gemini-3.8-Flash is not listed because its v1.1 runs are not yet complete.
The task reward is r = C × max(0, 1 − Tcandidate / Tbaseline), where C is 1 if the program passes the verifier's correctness checks. Score@1 is the mean reward over the 32 tasks; Aτ is the share of tasks that are correct and at least τ× faster; GM is the geometric mean speedup, counting incorrect or unaccelerated outcomes as 1×.
| Task | Directory | Area | CPUs | Memory | Verifier limit |
|---|---|---|---|---|---|
| GROMACS | gromacs-molecular-dynamics |
Molecules & materials | 4 | 6 GiB | 390 min |
| LAMMPS | lammps-molecular-dynamics |
Molecules & materials | 4 | 8 GiB | 30 min |
| GPAW | gpaw-fd-dft-restart |
Molecules & materials | 4 | 6 GiB | 233 min |
| Quantum ESPRESSO | qe-scf-nscf-dos |
Molecules & materials | 4 | 6 GiB | 233 min |
| SIESTA | siesta-dft-restart |
Molecules & materials | 4 | 6 GiB | 233 min |
| Fluidity | fluidity-heat-checkpoint |
Fluids & atmosphere | 4 | 8 GiB | 233 min |
| ICON | icon-atmosphere-checkpoint |
Fluids & atmosphere | 4 | 6 GiB | 200 min |
| MPAS-A | mpas-atmosphere-restart |
Fluids & atmosphere | 4 | 6 GiB | 233 min |
| NEMO | nemo-lock-exchange |
Fluids & atmosphere | 4 | 8 GiB | 233 min |
| OpenFOAM | openfoam-cavity-piso |
Fluids & atmosphere | 4 | 8 GiB | 40 min |
| Palabos | palabos-lattice-boltzmann |
Fluids & atmosphere | 4 | 6 GiB | 120 min |
| SU2 | su2-transonic-euler |
Fluids & atmosphere | 4 | 8 GiB | 233 min |
| OpenMC | openmc-multigroup-transport |
Transport & astronomy | 4 | 6 GiB | 120 min |
| ShengBTE | shengbte-phonon-transport |
Transport & astronomy | 4 | 6 GiB | 233 min |
| VPIC | vpic-harris-reconnection |
Transport & astronomy | 4 | 6 GiB | 150 min |
| PRESTO | presto-pulsar-search |
Transport & astronomy | 4 | 6 GiB | 120 min |
| ABySS | abyss-genome-assembly |
Bioinformatics | 4 | 8 GiB | 30 min |
| MHM2 | mhm2-metagenome-assembly |
Bioinformatics | 4 | 6 GiB | 150 min |
| MrBayes | mrbayes-phylogenetics |
Bioinformatics | 4 | 6 GiB | 120 min |
| wtdbg2 | wtdbg2-long-read-assembly |
Bioinformatics | 4 | 8 GiB | 30 min |
| HPCG-derived | hpcg-multigrid-pcg |
Numerics & graphs | 4 | 6 GiB | 120 min |
| HPL-derived | hpl-dense-lu |
Numerics & graphs | 4 | 6 GiB | 120 min |
| Graph sparsification | fegrass-graph-sparsification |
Numerics & graphs | 4 | 4 GiB | 120 min |
| miniVite | minivite-louvain |
Numerics & graphs | 4 | 6 GiB | 120 min |
| NUFFT imaging | nufft-imaging |
Numerics & graphs | 4 | 6 GiB | 200 min |
| Tucker reconstruction | tucker-reconstruction |
Numerics & graphs | 8 | 16 GiB | 120 min |
| QuEST | quest-circuit-simulation |
Quantum circuits | 4 | 8 GiB | 60 min |
| QiboTN | qibotn-tensor-network-circuits |
Quantum circuits | 8 | 32 GiB | 833 min |
| Paged LM generation | paged-lm-generation |
Machine learning | 4 | 6 GiB | 200 min |
| ThunderSVM | thundersvm-train-predict |
Machine learning | 4 | 8 GiB | 60 min |
| DataLife | datalife-io-monitoring |
Scientific I/O | 4 | 6 GiB | 233 min |
| IO500-derived | io500-file-io |
Scientific I/O | 4 | 6 GiB | 120 min |
Every task gives the agent eight hours. CPUs and memory are the agent's allocation; the verifier limit is the private verifier's time limit. HPCG-derived, HPL-derived and IO500-derived are adapted tasks, not official competition benchmark scores.
| File | Contents |
|---|---|
accelerate-bench-v1.1-harbor-tasks.tar.gz |
The 32 task packages under canonical/tasks/, canonical/manifest.json (path, size, mode and SHA-256 of every task file), licenses, citation metadata and contamination markers |
third-party-sources/fluidity-ppa-sources.tar |
Source packages of the Ubuntu packages bundled with the Fluidity task |
SHA256SUMS, third-party-sources/SHA256SUMS |
Checksums of the two archives |
task-catalog.json, source-cohort.json, canary-metadata.json, canaries.json |
Task list, release provenance and contamination markers |
LICENSE, notices/ |
Component license terms and third-party notices |
Version 1.1 starts from task source 20261010-v5-timing3 and includes the later v1.1 revisions of MHM2 (task version 1.1.1: statement, correctness checks and reference source), Fluidity (output parser; Ubuntu dependencies bundled in .fluidity-ppa/), SU2 (verifier time limit) and IO500 (system-call trace parser). The v1.1 release notes describe each change.
Original author-owned code and tools use Apache-2.0; the manuscript uses CC BY 4.0. Bundled third-party code, data and models keep their component licenses, including ABySS's noncommercial GPL-derived terms, ICON file-level exceptions and HPL acknowledgements; the aggregate is therefore labeled license: other. Several Ubuntu packages bundled with the Fluidity task are LGPL or GPL licensed, and their source packages are in third-party-sources/. Access approval does not grant additional third-party rights.
The release carries one release-level and 32 task-level canary markers, including the one at the top of this card. Please keep them when managing evaluation copies, and exclude the tasks from training corpora. The code repository includes a scanner (tools/scan_canaries.py); a hit shows that the text is present, not that a model was trained on it.
@misc{liu2026acceleratebench,
  title  = {Accelerate Bench: Evaluating Agents for Application-Level Program Optimization},
  author = {Liu, Bowen and Li, Yuhan and Chen, Nuo and Luo, Weile and Peng, Miao and Zhang, Qintong and Zhang, Qifan and Li, Jia and Gao, Ziqi and Huang, Lydell},
  year   = {2026},
  eprint = {2611.20882},
  archivePrefix = {arXiv},
  primaryClass = {cs.AI},
  url    = {https://arxiv.org/abs/2611.20882}
}
Accelerate Bench 评测编码 agent 能否在保持结果正确的前提下,让完整的科学计算应用跑得更快。本数据集为论文评测所用的 v1.1 版本,共 32 道题,以 Harbor 任务包的形式发布(约 2.56 GB)。每道题给出可运行的应用、固定工作负载和 CPU/内存预算,agent 有 8 小时优化;私有验证器重新构建最终程序,在隐藏输入上检查正确性,并与未修改的程序交替计时。
Harbor Hub: 除 ICON 外的 31 道题已公开发布为 Harbor 数据集 accelerate-bench/accelerate-bench,无需申请,按上方 harbor run -d accelerate-bench/accelerate-bench@v1.1 命令即可运行。ICON 的两份网格文件需从官方来源下载,因此只在完整发布包中提供。
申请访问: 完整发布包含全部 32 道题及每个文件的 SHA-256 清单。在上方表单填写单位(无隶属可填 Independent)与计划开展的评测,人工审核。允许模型评测、复现、审计与教学;请勿将题目用于预训练、微调、蒸馏或强化学习训练,不公开再分发发布包。完整的访问承诺与隐私说明见上方折叠内容。
下载与运行: 获批后推荐使用代码仓库中的 scripts/download_data.py 下载并逐文件校验;也可按上方命令用 hf download 下载固定版本并核对 SHA256。运行方法见 GitHub 快速上手。
版本与许可: v1.1 在任务源码 20261010-v5-timing3 的基础上,包含 MHM2、Fluidity、SU2 和 IO500 四题的 v1.1 修订。自有代码采用 Apache-2.0,论文采用 CC BY 4.0,第三方组件保留原许可;Fluidity 附带的 Ubuntu 软件包中有 LGPL/GPL 组件,对应源码包见 third-party-sources/。