
Sabich trained forward from its previous weights on all recordings so far. The Hebrish apps default since 2026-11-02.
AI & ML interests
Improving voice AI accuracy for code-switched English-Hebrew for English-speaking immigrants in Israel and the Jewish world. Models: ASR (focus), TTS ( POC / experimentary).
Recent Activity
View all activity
Organization Card

Hebrish · עבריש
Dictation that gets the Hebrew words right.
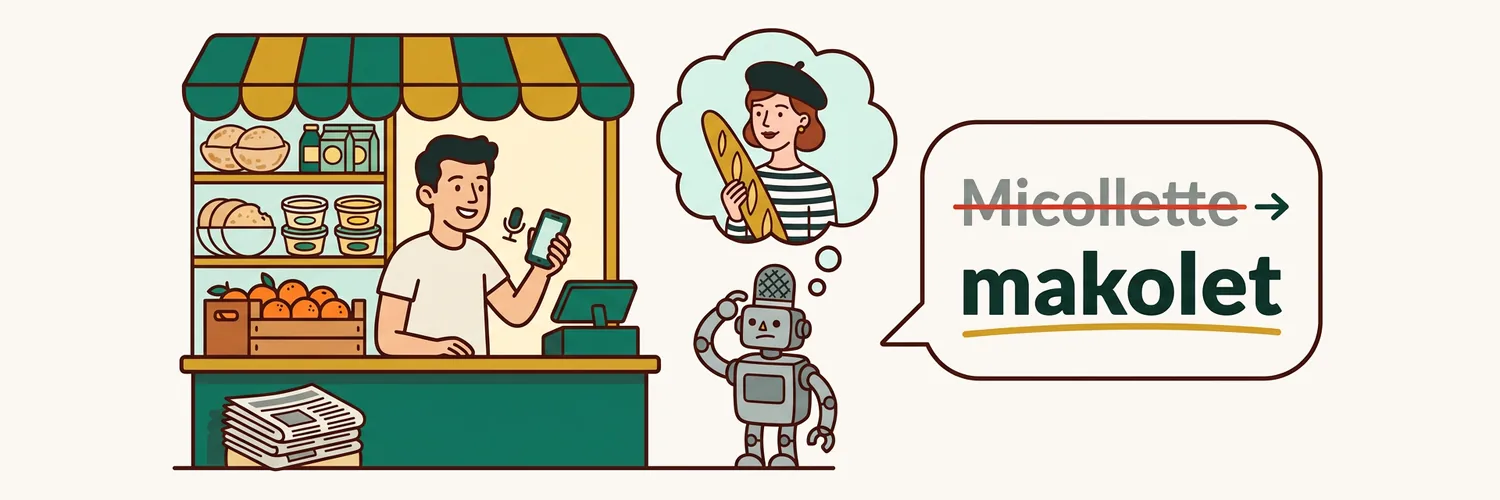
Ordinary dictation hears makolet and writes "Micollette". Hebrish writes the Hebrew word.
Hebrish builds open speech tools for code-switched English–Hebrew, for English-speaking immigrants in Israel and users throughout the Jewish world: speech recognition (ASR) that writes the Hebrew words correctly, and speech synthesis (TTS) that says them correctly. It is a one-person, not-for-profit project by Daniel Rosehill, and its models and data are open.
- Models: see them all on one page in the Hebrish Models Space.
- Speech recognition (ASR):
- Sabich (Rolling), the default in the apps since 2026-11-02: Sabich trained further from its own weights on each new batch of recordings.
- Sabich (Stable), the established release: code-switching plus tech vocabulary. Try either in your browser in the Sabich demo. The Sabich line comes in variants for every size of device: Qwen3-ASR-1.7B and Canary-Qwen-2.5B for desktop GPUs, Parakeet-110M for small devices, and asr4all-S and -M for wearables.
- Jachnun: code-switching only.
- Shakshuka: streaming, so the words appear while you speak.
- Whisper Hebrish: Whisper fine-tunes, where the project started.
- On-device builds (GGUF, ONNX, sherpa-onnx, MLX) are in
-<format>repos. Which model should I use?
- Speech synthesis (TTS):
- Meorav: code-switching text-to-speech, a Qwen3-TTS fine-tune that reads code-switched English aloud and pronounces the Hebrew words in it correctly. Meorav PoC-1 is the first checkpoint: experimental, open (CC BY-NC 4.0), no benchmark yet. Training code: Meorav-TTS.
- A token classifier that finds romanized Hebrew words in English text, for text-to-speech.
- Data: read-aloud code-switching sentences and a frozen benchmark, scored by Hebrew-term recall on a clean subset. Also every Israeli street name (national list with English names from OpenStreetMap), the vocabulary source for street sentences. Results: hebrish.app/benchmarks.
- Apps: Hebrish runs the models on-device on Android, Linux and Windows.
Contribute your voice
More voices and accents make the models better for everyone. Recording in the Hebrish capture app with consent given? Your takes are added through your settings; nothing more to do.
To send a batch of your own recordings, open a pull request on Hebrish/Community-Voice-Contributions: one folder per Hugging Face username, audio plus a metadata.jsonl. It is the only Hebrish dataset that accepts pull requests; we review each one and integrate the recordings into the datasets. Instructions on the dataset card and at hebrish.app/get-involved.
Everything in one place, including repos still on Daniel's personal account: the Hebrish collection.
Website: hebrish.app · GitHub: Hebrish-ASR
spaces 8
pinned
Running
Hebrish: try Sabich
🥙
English dictation with Hebrew words, tech terms and numbers
pinned
Running
Hebrish: try Jachnun
🫓
English dictation that gets the Hebrew words right
pinned
Running
Hebrish Models
🥙
Every Hebrish English-Hebrew code-switching speech model
Running
English-Hebrew Code-Switching Parakeet
🦜
Versions, downloads, results and notes for the fine-tune
Running
Parakeet Training Data Map
🗺
Master dataset, modular subsets, fine-tune blends
models 31

Hebrish/Sabich-Rolling-sherpa-onnx-int8
Automatic Speech Recognition • Updated
Hebrish/Sabich-Rolling-ONNX
Updated
Hebrish/Sabich-Rolling
Automatic Speech Recognition • Updated
Hebrish/Sabich-sherpa-onnx-int8
Automatic Speech Recognition • Updated
Hebrish/Sabich
Automatic Speech Recognition • Updated • 408 • 1
Hebrish/Sabich-ONNX
Automatic Speech Recognition • Updated • 8
Hebrish/Sabich-GGUF
Automatic Speech Recognition • 0.6B • Updated • 8
Hebrish/Sabich-MLX
Automatic Speech Recognition • 0.6B • Updated • 2
Hebrish/Whisper-Hebrish-Small-ACFT
Automatic Speech Recognition • 0.2B • Updated • 35
Hebrish/Nemotron-Speech-Streaming-EN-0.6B-English-Hebrew-Codeswitching
Automatic Speech Recognition • Updated • 120
datasets 42
Hebrish/Hebrish-Validation
Updated
Hebrish/Noisy-Condition-Sentences
Viewer • Updated • 3.68k • 338
Hebrish/Yiddish-Sentences
Viewer • Updated • 271 • 315
Hebrish/ASR-Error-List
Updated • 273 • 1
Hebrish/Israeli-Name-Sentences
Updated • 198
Hebrish/Jewish-Religious-Terminology-Sentences
Viewer • Updated • 1.91k • 486
Hebrish/Irish-English-Sentences
Viewer • Updated • 247 • 334
Hebrish/Pronunciation-Variants
Viewer • Updated • 152 • 169
Hebrish/Hebrish-Ideas
Updated • 318
Hebrish/Community-Voice-Contributions
Viewer • Updated • 1