

metadata
license: other
license_name: bespoke-lora-trained-license
license_link: >-
  https://multimodal.art/civitai-licenses?allowNoCredit=True&allowCommercialUse=Rent&allowDerivatives=True&allowDifferentLicense=False
tags:
  - text-to-image
  - stable-diffusion
  - lora
  - diffusers
  - template:sd-lora
  - concept
  - action figure
  - figure
  - toy
  - concpet
  - xl lora
base_model: stabilityai/stable-diffusion-xl-base-1.0
instance_prompt: toy
widget:
  - text: ' toy, photo George w bush mission accomplished'
    output:
      url: 3328637.jpeg
  - text: ' toy fall autumn pepe'
    output:
      url: 3328917.jpeg
  - text: ' toy, photo goku on a skateboard,'
    output:
      url: 3328638.jpeg
  - text: ' toy bill Clinton Saxaphone'
    output:
      url: 3329095.jpeg
  - text: ' toy dogs playing poker'
    output:
      url: 3328796.jpeg
  - text: ' toy photo nicolas cage car'
    output:
      url: 3328734.jpeg
Doctor Diffusion's Toy XL Style LoRA
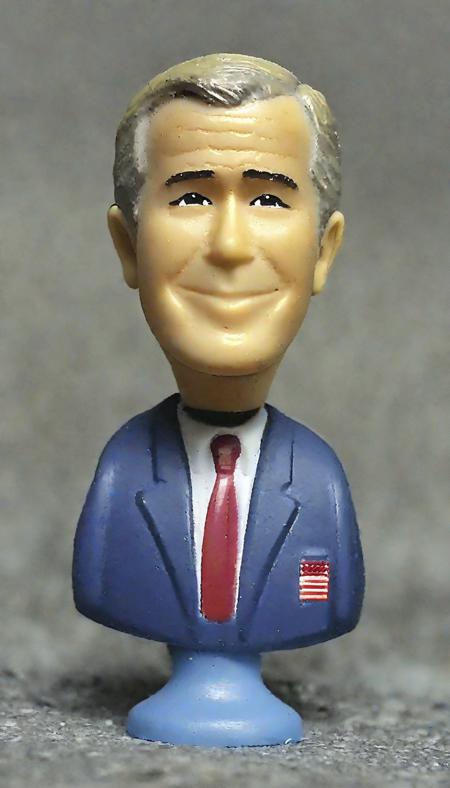
- Prompt
- toy, photo George w bush mission accomplished
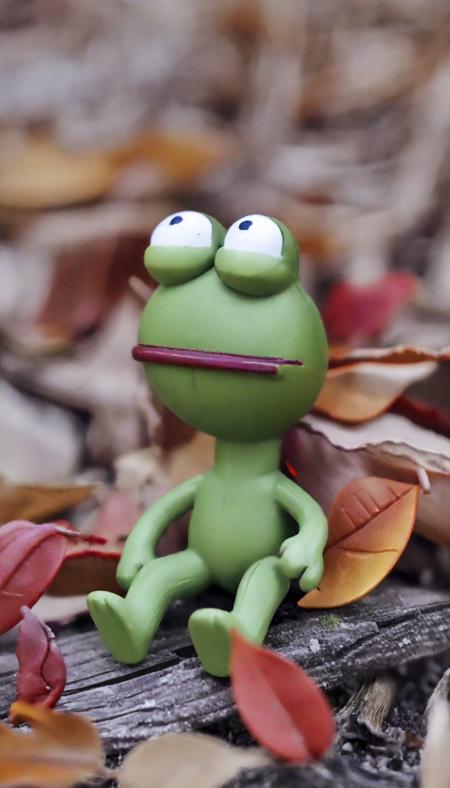
- Prompt
- toy fall autumn pepe
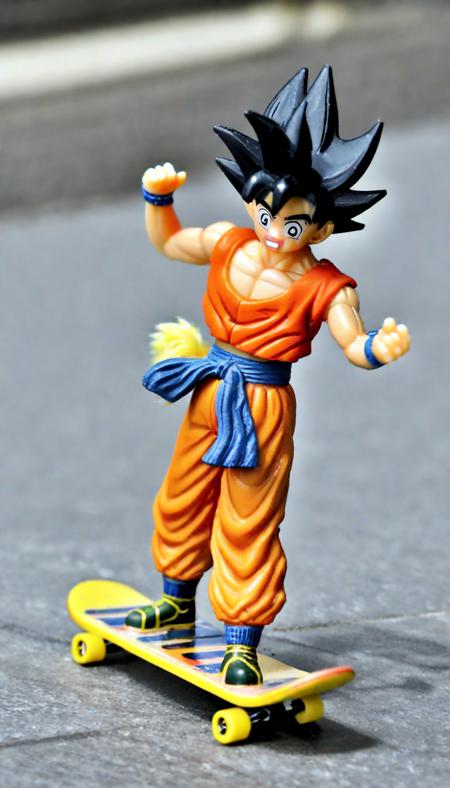
- Prompt
- toy, photo goku on a skateboard,
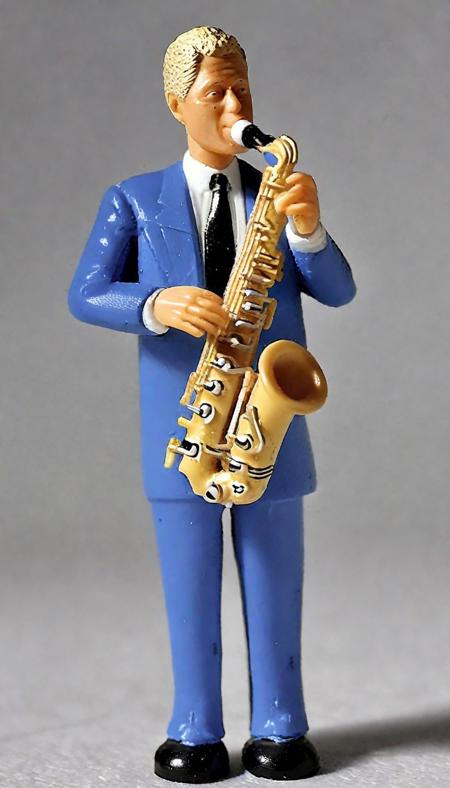
- Prompt
- toy bill Clinton Saxaphone
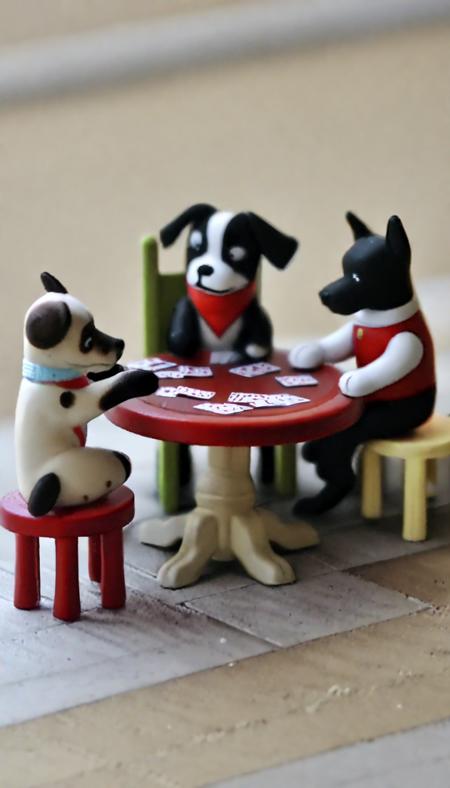
- Prompt
- toy dogs playing poker
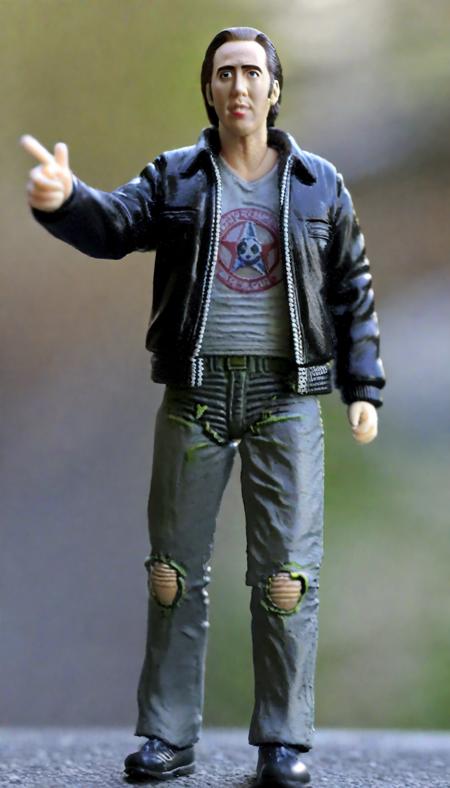
- Prompt
- toy photo nicolas cage car
Model description
Use "toy" in prompt.
☕ Like what I do? ☕
☕ Buy me a coffee or two! ☕
Trigger words
You should use toy, photo to trigger the image generation.
Download model
Weights for this model are available in Safetensors format.
Download them in the Files & versions tab.
Use it with the 🧨 diffusers library
from diffusers import AutoPipelineForText2Image
import torch

pipeline = AutoPipelineForText2Image.from_pretrained('stabilityai/stable-diffusion-xl-base-1.0', torch_dtype=torch.float16).to('cuda')
pipeline.load_lora_weights('DoctorDiffusion/doctor-diffusion-s-toy-xl-style-lora', weight_name='DD-toy-v2.safetensors')
image = pipeline(' toy photo nicolas cage car').images[0]
For more details, including weighting, merging and fusing LoRAs, check the documentation on loading LoRAs in diffusers