


Upload 3 files
Browse files- .gitattributes +1 -0
- README.md +31 -14
- assets/dflash_system.png +3 -0
- assets/speedup.png +0 -0
.gitattributes
CHANGED
|
@@ -33,3 +33,4 @@ saved_model/**/* filter=lfs diff=lfs merge=lfs -text
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
|
|
|
|
|
| 33 |
*.zip filter=lfs diff=lfs merge=lfs -text
|
| 34 |
*.zst filter=lfs diff=lfs merge=lfs -text
|
| 35 |
*tfevents* filter=lfs diff=lfs merge=lfs -text
|
| 36 |
+
assets/dflash_system.png filter=lfs diff=lfs merge=lfs -text
|
README.md
CHANGED
|
@@ -1,31 +1,26 @@
|
|
| 1 |
---
|
| 2 |
-
language:
|
| 3 |
-
- en
|
| 4 |
-
- zh
|
| 5 |
license: apache-2.0
|
| 6 |
-
|
| 7 |
tags:
|
| 8 |
- speculative-decoding
|
| 9 |
- diffusion
|
| 10 |
- efficiency
|
| 11 |
-
-
|
| 12 |
-
-
|
|
|
|
| 13 |
---
|
| 14 |
|
| 15 |
# Qwen3-8B-DFlash-b16
|
|
|
|
| 16 |
|
| 17 |
-
**DFlash** is a lightweight **block diffusion** model
|
| 18 |
|
| 19 |
This model is the **drafter** component. It must be used in conjunction with the target model `Qwen/Qwen3-8B`.
|
| 20 |
|
| 21 |
<div align="center">
|
| 22 |
-
|
| 23 |
-
| [**Paper (Coming Soon)**](#) | [**GitHub**](https://github.com/z-lab/dspec-dev) |
|
| 24 |
-
|
| 25 |
</div>
|
| 26 |
|
| 27 |
-
**TL;DR:** In this work, we introduce **DFlash**, a method utilizing a lightweight **block diffusion** model for drafting in speculative decoding. This enables efficient and high-quality parallel drafting, pushing the limits of speculative decoding. DFlash achieves up to **6.02×** speedup on **Qwen3-8B**, nearly **2.5×** faster than the SOTA speculative decoding method **EAGLE-3**.
|
| 28 |
-
|
| 29 |
## 🚀 Quick Start
|
| 30 |
|
| 31 |
This model requires `trust_remote_code=True` to load the custom architecture for block diffusion generation.
|
|
@@ -36,14 +31,14 @@ Ensure you have `transformers` and `torch` installed. Our evaluation is conducte
|
|
| 36 |
pip install transformers==4.57.3 torch==2.9.0
|
| 37 |
```
|
| 38 |
|
| 39 |
-
###
|
| 40 |
The following example demonstrates how to load the DFlash drafter and the Qwen3-8B target model to perform speculative decoding.
|
| 41 |
```python
|
| 42 |
import torch
|
| 43 |
from transformers import AutoModel, AutoModelForCausalLM, AutoTokenizer
|
| 44 |
|
| 45 |
# 1. Load the DFlash Draft Model
|
| 46 |
-
# Note: trust_remote_code=True is required for
|
| 47 |
model = AutoModel.from_pretrained(
|
| 48 |
"z-lab/Qwen3-8B-DFlash-b16",
|
| 49 |
trust_remote_code=True,
|
|
@@ -90,3 +85,25 @@ generate_ids = model.spec_generate(
|
|
| 90 |
|
| 91 |
print(tokenizer.decode(generate_ids[0], skip_special_tokens=True))
|
| 92 |
```
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 1 |
---
|
|
|
|
|
|
|
|
|
|
| 2 |
license: apache-2.0
|
| 3 |
+
library_name: transformers
|
| 4 |
tags:
|
| 5 |
- speculative-decoding
|
| 6 |
- diffusion
|
| 7 |
- efficiency
|
| 8 |
+
- flash-decoding
|
| 9 |
+
- qwen
|
| 10 |
+
- diffusion-language-model
|
| 11 |
---
|
| 12 |
|
| 13 |
# Qwen3-8B-DFlash-b16
|
| 14 |
+
[**Paper (Coming Soon)**](#) | [**GitHub**](https://github.com/z-lab/dspec-dev) | [**Blog**](https://z-lab.ai/projects/dflash/)
|
| 15 |
|
| 16 |
+
**DFlash** is a novel speculative decoding method that utilizes a lightweight **block diffusion** model for drafting. It enables efficient, high-quality parallel drafting that pushes the limits of inference speed.
|
| 17 |
|
| 18 |
This model is the **drafter** component. It must be used in conjunction with the target model `Qwen/Qwen3-8B`.
|
| 19 |
|
| 20 |
<div align="center">
|
| 21 |
+
<img src="assets/dflash_system.png" alt="DFlash Architecture" width="100%">
|
|
|
|
|
|
|
| 22 |
</div>
|
| 23 |
|
|
|
|
|
|
|
| 24 |
## 🚀 Quick Start
|
| 25 |
|
| 26 |
This model requires `trust_remote_code=True` to load the custom architecture for block diffusion generation.
|
|
|
|
| 31 |
pip install transformers==4.57.3 torch==2.9.0
|
| 32 |
```
|
| 33 |
|
| 34 |
+
### Inference Example
|
| 35 |
The following example demonstrates how to load the DFlash drafter and the Qwen3-8B target model to perform speculative decoding.
|
| 36 |
```python
|
| 37 |
import torch
|
| 38 |
from transformers import AutoModel, AutoModelForCausalLM, AutoTokenizer
|
| 39 |
|
| 40 |
# 1. Load the DFlash Draft Model
|
| 41 |
+
# Note: trust_remote_code=True is required for DFlash. We recommend run on one GPU currently.
|
| 42 |
model = AutoModel.from_pretrained(
|
| 43 |
"z-lab/Qwen3-8B-DFlash-b16",
|
| 44 |
trust_remote_code=True,
|
|
|
|
| 85 |
|
| 86 |
print(tokenizer.decode(generate_ids[0], skip_special_tokens=True))
|
| 87 |
```
|
| 88 |
+
|
| 89 |
+
## Evaluation
|
| 90 |
+
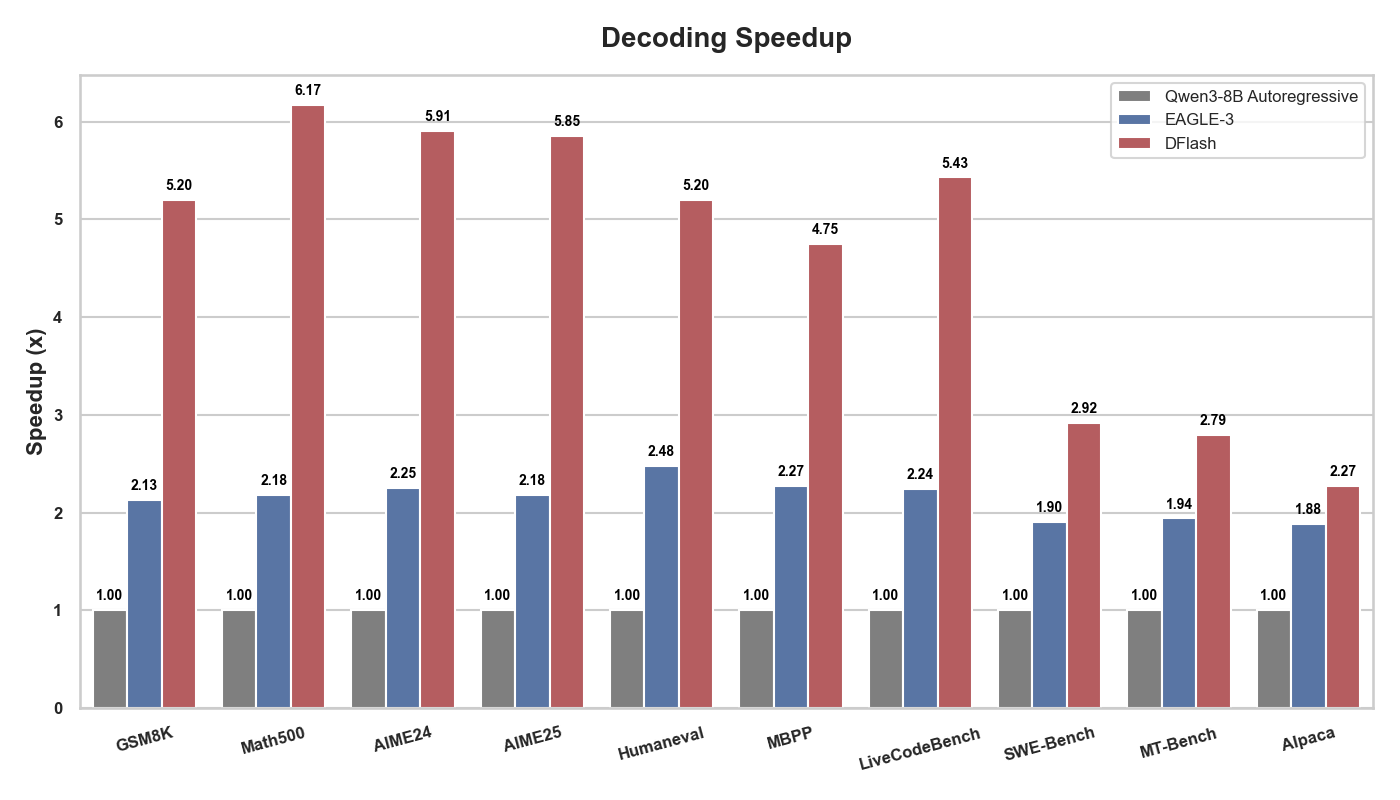
DFlash achieves up to **6.17$\times$** lossless acceleration for **Qwen3-8B**, making it nearly **2.5$\times$** faster than the state-of-the-art speculative decoding method EAGLE-3. Check out our [GitHub repository](https://github.com/z-lab/dflash) to see how to reproduce the results.
|
| 91 |
+
|
| 92 |
+
<div align="center">
|
| 93 |
+
<img src="assets/speedup.png" alt="DFlash Architecture" width="100%">
|
| 94 |
+
</div>
|
| 95 |
+
|
| 96 |
+
|
| 97 |
+
## **Citation**
|
| 98 |
+
If you find DFlash useful for your research or applications, please cite our project. The full paper is coming soon!
|
| 99 |
+
|
| 100 |
+
```bibtex
|
| 101 |
+
@article{chen2026dflash,
|
| 102 |
+
title = {DFlash: Block Diffusion for Flash Speculative Decoding},
|
| 103 |
+
author = {Chen, Jian and Liu, Zhijian},
|
| 104 |
+
journal = {arXiv preprint},
|
| 105 |
+
year = {2026},
|
| 106 |
+
url = {[https://github.com/z-lab/dflash](https://github.com/z-lab/dflash)},
|
| 107 |
+
note = {Paper coming soon}
|
| 108 |
+
}
|
| 109 |
+
```
|
assets/dflash_system.png
ADDED

|
Git LFS Details
|
assets/speedup.png
ADDED
|