

MiniCPM-V 4.7
Collection
A new chapter in on-device multimodal Al. • 15 items • Updated • 64
This repository hosts the GGUF (llama.cpp) quantized version of MiniCPM-V 4.7 1B. For the original BF16 weights and the full model card, please refer to openbmb/MiniCPM-V-4.7-1B.
GitHub · Evaluation · Examples · Usage · Model weights · DSpark-gguf
MiniCPM-V 4.7 is the latest model in the MiniCPM-V series, available in a 1B variant. It builds on the family's single-image, multi-image, and video understanding capabilities, combining stronger foundation capabilities with efficient visual encoding and on-device inference. Notable features of MiniCPM-V 4.7 include:
Model weights · Inference · Fine-tuning · Live demo · Local deployment · API · Cookbook
Significantly Advancing the Performance–Efficiency Pareto Frontier
The 1B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier. In Instruct mode, 1B substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency.
Overall Performance (1B, Instruct)
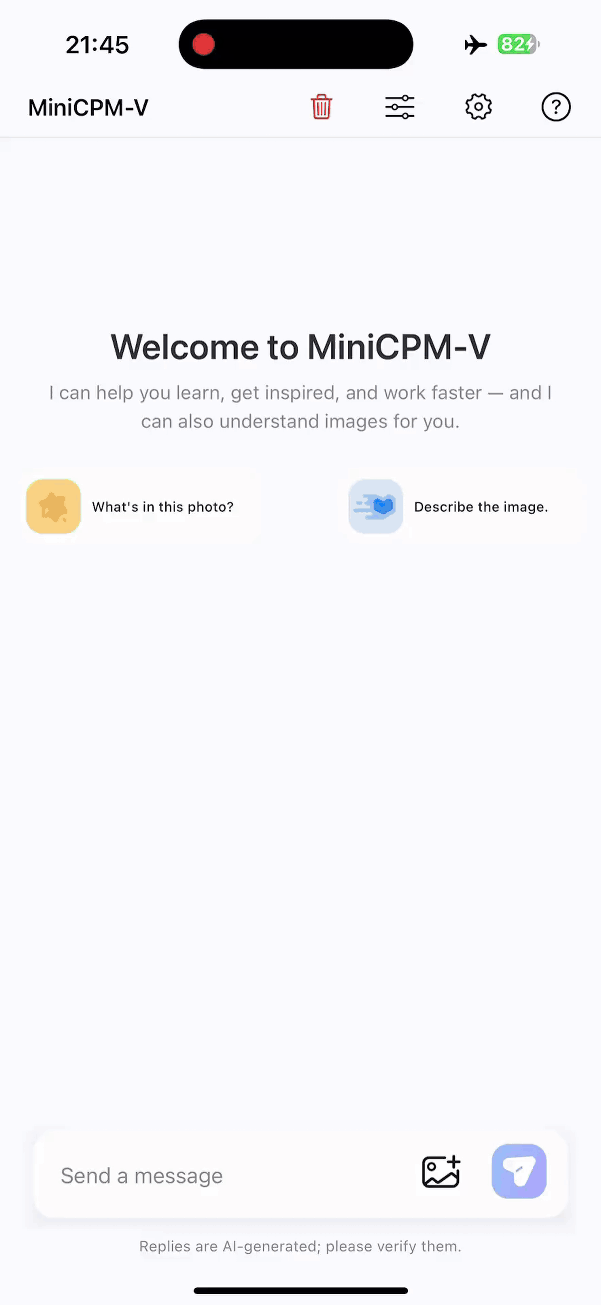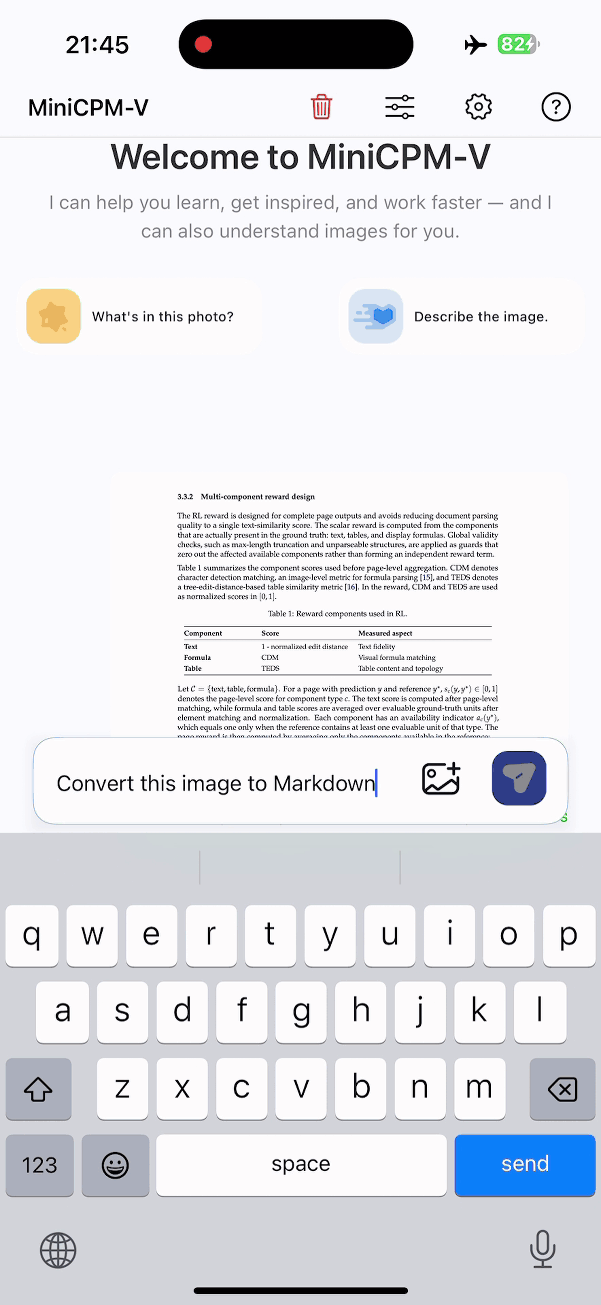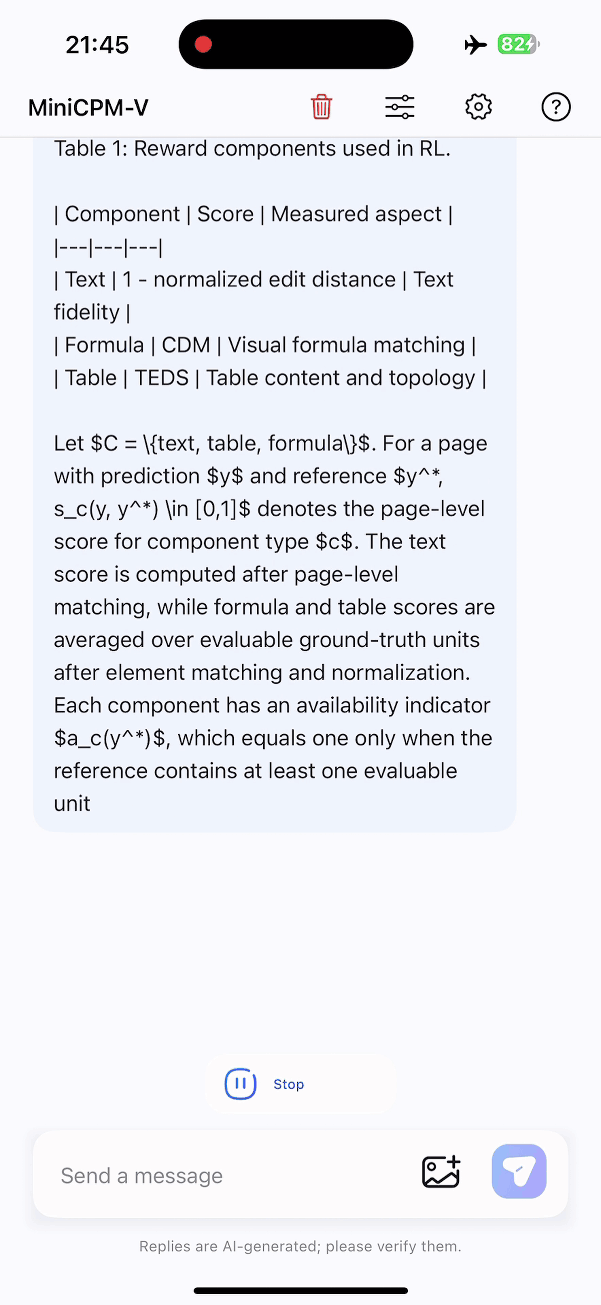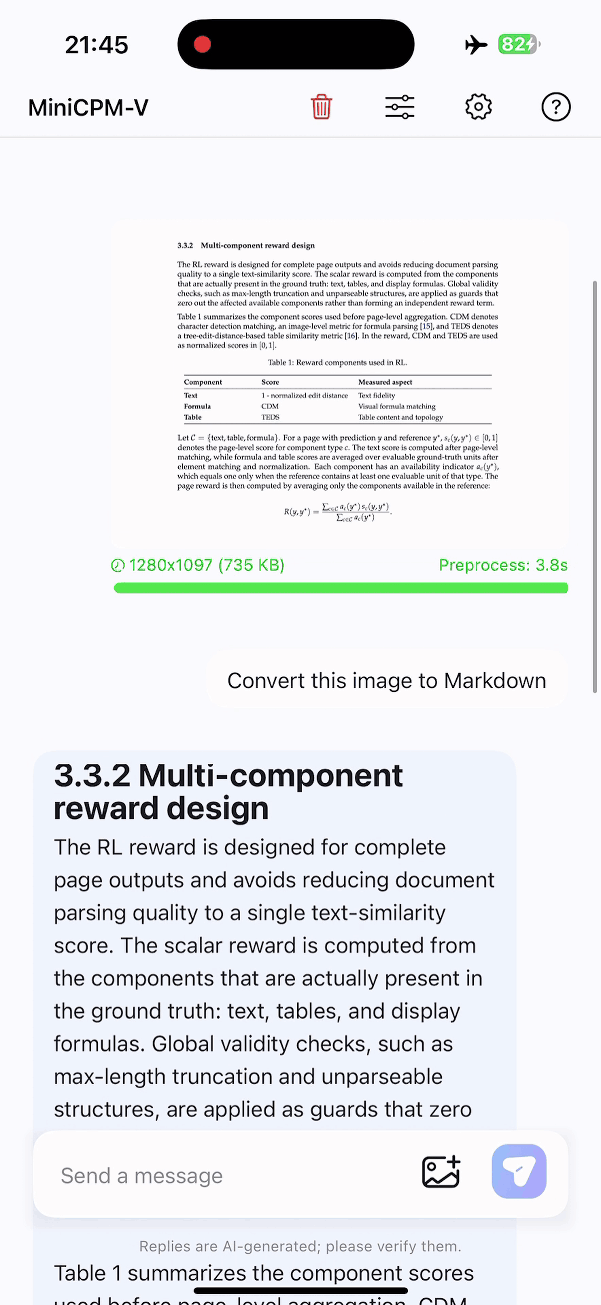
MiniCPM-V 4.7 can run on phones and tablets. The clips below are unedited screen recordings captured directly on the devices.
| 1B iPhone 17 Pro Max |
 |
pip install "transformers[torch]>=5.18.0" torchvision torchcodec
Note on CUDA compatibility:
torchcodec(used for video decoding) may have compatibility issues with certain CUDA versions. For example,torch>=2.11bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such asRuntimeError: Could not load libtorchcodec. Two workarounds:
- Replace
torchcodecwithPyAV— supports both image and video inference without CUDA version constraints:pip install "transformers[torch]>=5.18.0" torchvision av- Pin the CUDA version when installing torch to match your environment (e.g. CUDA 12.8):
pip install "transformers>=5.18.0" torchvision torchcodec --index-url https://download.pytorch.org/whl/cu128
import torch
from transformers import AutoModelForImageTextToText, AutoProcessor

model_id = "openbmb/MiniCPM-V-4.7-1B"

processor = AutoProcessor.from_pretrained(model_id)
model = AutoModelForImageTextToText.from_pretrained(
    model_id, torch_dtype="auto", device_map="auto"
)

# Flash Attention 2 is recommended for faster inference and lower GPU memory usage,
# especially in multi-image and video scenarios.
# model = AutoModelForImageTextToText.from_pretrained(
#     model_id,
#     torch_dtype=torch.bfloat16,
#     attn_implementation="flash_attention_2",
#     device_map="auto",
# )
messages = [
    {
        "role": "user",
        "content": [
            {"type": "image", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"},
            {"type": "text", "text": "What causes this phenomenon?"},
        ],
    }
]

downsample_mode = "16x"  # Using `downsample_mode="4x"` for Finer Detail

inputs = processor.apply_chat_template(
    messages, tokenize=True, add_generation_prompt=True,
    return_dict=True, return_tensors="pt",
    downsample_mode=downsample_mode,
    max_slice_nums=36,
    enable_thinking=False,
).to(model.device)

generated_ids = model.generate(
    **inputs,
    downsample_mode=downsample_mode,
    max_new_tokens=512,
    # recommended instruct-mode sampling parameters
    do_sample=True,
    temperature=0.7,
    top_p=0.95,
    top_k=100,
    min_p=0.0,
    presence_penalty=0,
    repetition_penalty=1.03,
)
generated_ids_trimmed = [
    out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
messages = [
    {
        "role": "user",
        "content": [
            {"type": "video", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/football.mp4"},
            {"type": "text", "text": "Describe this video in detail. Follow the timeline and focus on on-screen text, interface changes, main actions, and scene changes."},
        ],
    }
]

downsample_mode = "16x"  # Using `downsample_mode="4x"` for Finer Detail

inputs = processor.apply_chat_template(
    messages, tokenize=True, add_generation_prompt=True,
    return_dict=True, return_tensors="pt",
    downsample_mode=downsample_mode,
    max_num_frames=128,
    stack_frames=1,
    max_slice_nums=1,
    use_image_id=False,
    enable_thinking=False,
).to(model.device)

generated_ids = model.generate(
    **inputs,
    downsample_mode=downsample_mode,
    max_new_tokens=2048,
    # recommended instruct-mode sampling parameters
    do_sample=True,
    temperature=0.7,
    top_p=0.95,
    top_k=100,
    min_p=0.0,
    presence_penalty=0,
    repetition_penalty=1.03,
)
generated_ids_trimmed = [
    out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
You can customize image/video processing by passing additional parameters to apply_chat_template:
| Parameter | Default | Applies to | Description |
|---|---|---|---|
downsample_mode |
"16x" |
Image & Video | Visual token downsampling. "16x" merges tokens for efficiency; "4x" keeps four times as many tokens for finer detail. Must also be passed to generate(). |
max_slice_nums |
9 |
Image & Video | Maximum number of slices when splitting a high-resolution image. Higher values preserve more detail for large images. Recommended: 36 for image, 1 for video. |
max_num_frames |
128 |
Video only | Maximum number of main frames sampled from the video. |
stack_frames |
1 |
Video only | Total sample points per second. 1 = main frame only (no stacking). N (N>1) = 1 main frame + N−1 sub-frames per second; the sub-frames are composited into a grid image and interleaved with main frames. Recommended: 3 or 5. |
use_image_id |
True |
Image & Video | Whether to prepend <image_id>N</image_id> tags before each image/frame placeholder. Recommended: True for image, False for video. |
Note:
downsample_modemust be passed to bothapply_chat_template(for correct placeholder count) andgenerate(for the vision encoder). All other parameters only need to be passed toapply_chat_template.
transformers serve
Hugging Face Transformers includes a lightweight OpenAI-compatible server for quick testing and moderate-load deployment.
pip install "transformers[serving]>=5.18.0"
Start the server:
transformers serve openbmb/MiniCPM-V-4.7-1B --port 8000 --host 0.0.0.0
Send a request:
curl -s http://localhost:8000/v1/chat/completions \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "openbmb/MiniCPM-V-4.7-1B",
    "messages": [{
      "role": "user",
      "content": [
        {"type": "image_url", "image_url": {"url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"}},
        {"type": "text", "text": "What causes this phenomenon?"}
      ]
    }]
  }'
Tool calling example:
curl -s http://localhost:8000/v1/chat/completions -H 'Content-Type: application/json' -d '{
  "model": "openbmb/MiniCPM-V-4.7-1B",
  "messages": [{"role": "user", "content": [
    {"type": "text", "text": "the weather of Beijing"}
  ]}],
  "tools": [{
    "type": "function",
    "function": {
      "name": "get_weather",
      "description": "Get the current weather for a given location",
      "parameters": {
        "type": "object",
        "properties": {
          "location": {"type": "string", "description": "City name"}
        },
        "required": ["location"]
      }
    }
  }]
}'
We recommend using the following set of sampling parameters for generation in instruct mode: temperature=0.7, top_p=0.95, top_k=100, min_p=0.0, presence_penalty=0, repetition_penalty=1.03.
Speculative decoding (DSpark): we also release MiniCPM-V-4.7-1B-DSpark, a DSpark draft model trained for MiniCPM-V-4.7-1B.
OpenVINO™ is an open-source toolkit for optimizing and deploying AI inference on Intel CPU/GPU/NPU platforms. OpenVINO provides day-0 support for MiniCPM-V-4.7 on Intel platforms with high-performance inference. See the OpenVINO™ Toolkit to get started. You can install and run the example with this notebook.
MiniCPM-V 4.7 supports deployment on iOS, Android, and HarmonyOS, with day-0 support for Rockchip, Houmo, Intel, AMD, and Arm chip platforms. See the edge deployment repository for the apps and source code.
For supported inference and training frameworks, see Supported Inference and Training Frameworks and API. The MiniCPM-V 4.7 Cookbook covers deployment, fine-tuning, and quantization workflows.
Task guides
Quantization
| Method | Guide |
|---|---|
| GGUF | Quantization guide |
| BNB | Quantization guide |
| AWQ | Quantization guide |
| GPTQ | Quantization guide |
| FP8 / INT4 | Quantization guide |
We would like to thank the following projects:
MiniCPM-V 4.7 is available in 35B-A3B and 1B variants. Each model is paired with its DSpark speculative decoding heads, available in BF16 and GGUF.
| Model | Description | Model weights | DSpark heads |
|---|---|---|---|
| MiniCPM‑V 4.7 35B-A3B |
The first open-source MoE model to run smoothly on-device without compromising performance, raising the bar for on-device performance. |
🤗  BF16 🤗 FP8🤗 int4🤗 AWQ🤗 GPTQ🤗 GGUF
|
🤗 BF16 🤗 GGUF
|
| MiniCPM‑V 4.7 1B |
Combines stronger capabilities with extremely high efficiency, advancing the performance–efficiency Pareto frontier for multimodal large language models. |
🤗 BF16 🤗 int4🤗 AWQ🤗 GPTQ🤗 GGUF
|
🤗 BF16 🤗 GGUF
|
The 1B int4 variant uses bitsandbytes; AWQ and GPTQ use W4A16 quantization. Quantized variants reduce memory usage; GGUF weights support CPU inference.
Also available on Ollama.
4-bit
5-bit
6-bit
8-bit
16-bit
Base model
openbmb/MiniCPM-V-4.7-1B